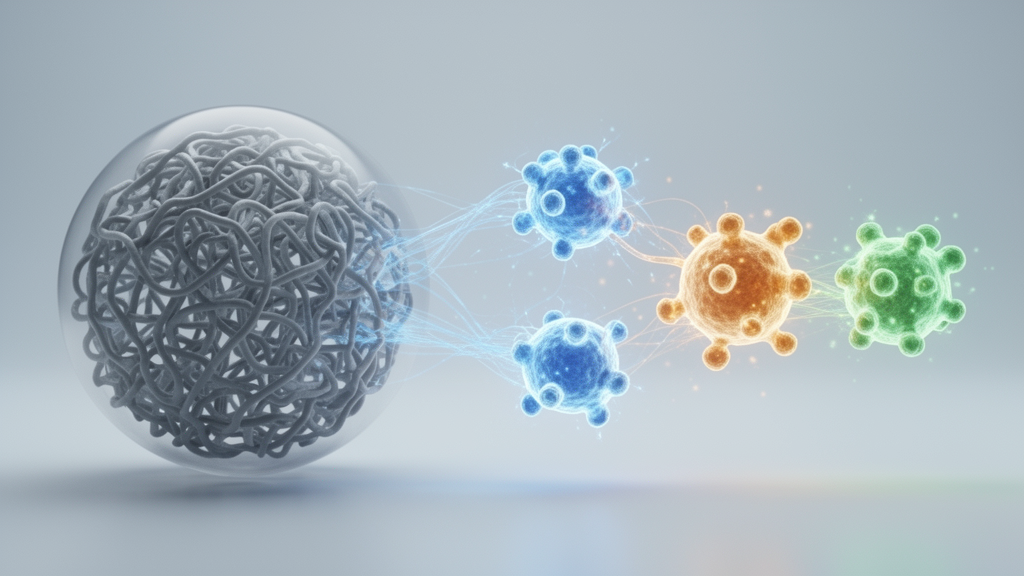
Researchers have introduced a computational framework called ESMF, short for Elastic Signature-based Matrix Factorization, designed to improve how scientists estimate which cell types are present in bulk RNA sequencing samples. The work, published in the journal BioData Mining on 17 October 2026, addresses a long-standing bottleneck in transcriptomics: bulk RNA-seq is affordable and scalable for large cohorts, but it averages signals across thousands of cells, hiding the cellular composition that often matters most for understanding tissue biology.
Single-cell RNA sequencing solves the resolution problem by measuring gene expression in individual cells, but it brings its own obstacles. The technology is technically complex, more expensive to deploy at scale, and vulnerable to tissue processing artifacts. The ESMF team, led by Shuchao Li, Yunwen Mou, Bingjie Yuan, Jinting Guan and Guoli Ji, positioned their method as a bridge between the two paradigms, using single-cell reference data to sharpen the interpretation of bulk profiles.
The framework rests on three technical pillars. First, it applies elastic expression signature-based regularization, which incorporates gene expression distribution parameters, specifically means and variances, drawn from single-cell RNA-seq reference data. Rather than treating a cell type’s signature as a single fixed vector, the method carries information about how expression varies across cells of that type, constraining the deconvolution solution in a way the authors describe as biologically grounded.
Second, ESMF models technical noise with a negative binomial distribution. Count data from RNA sequencing are famously overdispersed, meaning their variance exceeds what simpler models assume, and noise amplification has been a recurring weakness in existing deconvolution tools. By building an explicit noise model into the factorization itself, the method aims to keep measurement error from distorting the estimated cell proportions.
Third, the framework uses a dual-validation strategy for marker gene selection, integrating literature-curated knowledge with computational screening. Marker genes are the anchors that tie a bulk sample’s expression profile back to specific cell populations, and poor marker choices can propagate errors through the entire analysis. Combining curated biological knowledge with data-driven filtering is intended to make that anchoring step more reliable.
The authors evaluated ESMF across diverse synthetic and biological datasets using what they describe as a multi-tiered validation framework. According to the published results, the method showed competitive performance against established benchmarks, with three highlighted strengths: improved stability when applied across different sequencing platforms, enhanced detection of rare cell types in clinically relevant samples, and expression estimates that the authors characterize as biologically plausible.
Cross-platform stability matters because deconvolution tools trained on one sequencing technology often degrade when applied to data generated on another, a practical concern for labs combining datasets from different sources. Rare-cell detection is equally consequential, since rare but biologically important populations can be missed by methods that favor dominant cell types, and the authors report gains specifically in clinically relevant samples.
The team concludes that ESMF resolves both cellular proportions and cell-type-specific expression profiles with what they term biological fidelity, offering an analytical platform for translational investigation of the tissue microenvironment. Because the article was shared early as peer-reviewed, accepted research carrying a permanent DOI, it remains subject to further editorial edits before the final version of record replaces it.
As with any computational benchmark study, the reported advantages reflect performance on the synthetic and biological datasets the authors tested, and independent adoption across new tissue types and platforms will be the practical test of the method’s robustness. The full open-access article, including implementation details and validation results, is available from BioData Mining.
Subject of Research: A computational method, ESMF, for estimating cell-type composition and expression profiles from bulk RNA sequencing data using single-cell references.
Article Title: ESMF: Elastic Signature-based Matrix Factorization for Robust Cellular Deconvolution
Article References: Li, S., Mou, Y., Yuan, B., Guan, J., & Ji, G. (2026). ESMF: Elastic Signature-based Matrix Factorization for Robust Cellular Deconvolution. BioData Mining. https://doi.org/10.1186/s13040-026-00612-7
Image Credits: AI Generated
DOI: 10.1186/s13040-026-00612-7
Keywords: ESMF, cellular deconvolution, bulk RNA-seq, single-cell RNA-seq, matrix factorization, negative binomial model, marker genes, tissue microenvironment, bioinformatics, gene expression, BioData Mining, computational biology
Cite Scienmag News
Juliet Wilcox. (October 28, 2026). New ESMF Method Sharpens Cell-Type Estimates from Bulk RNA Sequencing Data. Scienmag. https://scienmag.com/new-esmf-method-sharpens-cell-type-estimates-from-bulk-rna-sequencing-data/
Juliet Wilcox. "New ESMF Method Sharpens Cell-Type Estimates from Bulk RNA Sequencing Data." Scienmag, 28 October 2026, https://scienmag.com/new-esmf-method-sharpens-cell-type-estimates-from-bulk-rna-sequencing-data/. Accessed 28 October 2026.
Juliet Wilcox. "New ESMF Method Sharpens Cell-Type Estimates from Bulk RNA Sequencing Data." Scienmag. October 28, 2026. https://scienmag.com/new-esmf-method-sharpens-cell-type-estimates-from-bulk-rna-sequencing-data/