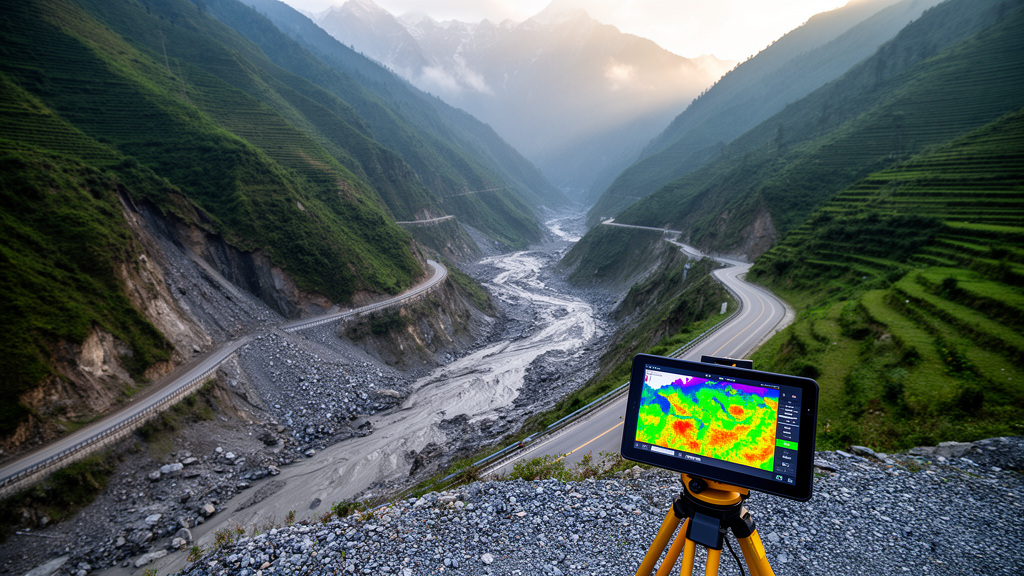
A stretch of highway cutting through one of the most tectonically active corners of the Himalaya has become the testing ground for a new generation of landslide hazard maps. In a study published in Discover Geoscience, researchers compared two machine learning models against a conventional expert-weighted technique to assess landslide susceptibility along the 123 kilometre National Highway 513 corridor that connects Pasighat to Yingkiong in Arunachal Pradesh, northeast India. The results were striking: the data-driven models discriminated between stable and unstable ground with a skill that the traditional method could not approach, while also exposing exactly how much of that apparent skill is an artefact of the way such models are usually tested.
The corridor itself is a demanding natural laboratory. It runs from the Sub-Himalayan foothills into Higher Himalayan crystalline terrain, with elevations ranging from roughly 84 to 1,803 metres above sea level. The geology along the route includes Precambrian metamorphic rocks, Paleozoic and Mesozoic intrusive bodies, Neogene molasse sediments and Quaternary colluvial deposits. Northeast to southwest trending thrusts and lineaments cut through the landscape, creating structural discontinuities and preferential seepage paths during intense rainfall. Mean annual rainfall rises from about 2,200 millimetres near Pasighat to more than 3,500 millimetres in the upper reaches, and field reconnaissance along the road identified rockfall, weathered-rock slide and debris-slide mechanisms on road-cut slopes.
To build the models, the team compiled a georeferenced inventory of 230 landslide initiation points drawn from Geological Survey of India Bhukosh point records, multitemporal Google Earth Pro imagery and field surveys. An equal number of 230 non-landslide points were randomly generated outside a 500 metre exclusion buffer, producing a balanced dataset. Twelve geoenvironmental conditioning factors, including slope gradient, aspect, curvature, relative relief, topographic wetness index, drainage density, distances to streams, roads and lineaments, land use and land cover, geology and lithology, were prepared in a GIS environment at 30 metre resolution. Variance inflation factor analysis confirmed that all factors had VIF values below 5, indicating acceptable independence among predictors.
The machine learning side of the comparison paired a multilayer perceptron artificial neural network with a Random Forest classifier. The neural network used two hidden layers with 64 and 32 neurons respectively, ReLU activation, L2 regularisation and dropout, and was trained with binary cross-entropy loss and Adam optimisation under early stopping. The Random Forest used 100 estimators with no depth constraint, with hyperparameters tuned by grid-search cross-validation. Both models were evaluated on a 70:30 train-test split using ROC-AUC, accuracy, precision, recall, F1-score and the Matthews correlation coefficient, a metric that is particularly informative for binary classification.
The Random Forest emerged as the strongest performer, achieving a predictive AUC of 0.980, accuracy of 0.954 and an MCC of 0.908. The neural network followed closely with a predictive AUC of 0.954, accuracy of 0.936 and MCC of 0.873. By contrast, the analytical hierarchy process, an expert-weighted method in which factors are scored through pairwise comparisons on Saaty’s 1 to 9 scale and combined through a linear weighted overlay, managed only a predictive AUC of 0.551, barely better than a random classifier. The AHP map classified 67.73 percent of the corridor as Very Low susceptibility and just 0.51 percent as Very High, producing broad continuous zones dominated by land use and geology rather than spatially focused hazard clusters.
Perhaps the most methodologically important contribution of the study is its treatment of spatial autocorrelation. Conventional random train-test splitting can inflate performance estimates when neighbouring samples share similar terrain and geological attributes. To quantify this, the researchers divided the corridor into five contiguous north-south blocks of roughly 24.6 kilometres each and ran five-fold spatial block cross-validation, withholding one block for testing in each fold. Under this stricter scheme, the neural network’s mean AUC dropped to 0.921 with a standard deviation of 0.028, and the Random Forest’s to 0.941 with a standard deviation of 0.022. The reduction of about 0.033 for the ANN confirms that spatial autocorrelation is present but mild, and reporting both values avoids overstating predictive skill.
The machine learning maps also painted a far more focused picture of where danger concentrates. The ANN classified 79.21 percent of the corridor as Very Low susceptibility, with 3.32 percent High and 1.43 percent Very High, concentrating the highest hazard around steep road-cut reaches and geologically weak shale-sandstone zones. The Random Forest map was similar, assigning 83.45 percent of the corridor to the Very Low class and 1.46 percent to Very High, and the two models showed strong spatial agreement in the location of high-susceptibility reaches, providing mutual support for the data-driven outputs. A learning-curve analysis, which trained the network on progressively larger subsets from 10 to 161 landslide samples, showed validation AUC stabilising near the full training count at 0.952 plus or minus 0.014, indicating the inventory was adequate for the chosen model complexity.
Feature importance analysis revealed a physically meaningful hierarchy of controls. Both models ranked slope gradient as the most important predictor, followed by land use and land cover, geology and drainage density, with aspect the least influential. The authors note that this ranking has a direct geotechnical basis: as slope angle increases, the downslope component of self-weight rises relative to resisting shear strength, and road cutting can further reduce stability by steepening the face or removing toe support. Intriguingly, the AHP matrix had assigned slope a low relative weight of just 0.031, because steep terrain is so widespread along the corridor that it discriminates poorly in a linear overlay. The researchers treat this discordance as a diagnostic result, showing that expert-weighted map production and data-driven factor learning can diverge in instructive ways.
Uncertainty was addressed through a bootstrap ensemble of 100 neural network models trained on resampled versions of the training data. For each pixel, the mean susceptibility probability and standard deviation across the ensemble were computed, and the coefficient of variation served as a normalised uncertainty measure. Zones where the coefficient exceeded 0.40 were flagged for priority field verification, particularly transitional reaches and corridor margins. The authors also stress that susceptibility zone percentages depend heavily on the classification scheme applied to the continuous probability surface: Jenks Natural Breaks allocated 1.43 percent of the corridor to the Very High class, equal interval allocated 3.41 percent, and quantile classification allocates 20 percent by definition. They therefore recommend treating the continuous probability surface as the most robust output, with classified maps used mainly for communication.
The study is explicit about its limits. It produces a static spatial susceptibility map and does not predict the timing of individual failures; temporal triggers such as antecedent rainfall, rainfall intensity, pore-water pressure and seismic acceleration were outside the scope of the baseline assessment. The 30 metre SRTM digital elevation model cannot resolve individual benches or small retaining structures, and higher-resolution Cartosat, UAV or LiDAR terrain data would improve site-scale interpretation. Even so, the work delivers a reproducible, uncertainty-aware framework for highway-slope screening in the Eastern Himalaya, one that its authors argue is transferable to other mountain-road corridors where landslide inventories and geospatial layers are available, and a clear demonstration that where adequate landslide data exist, inventory-driven machine learning is more defensible than expert judgement alone.
Subject of Research: Landslide susceptibility mapping along the NH-513 highway corridor in Arunachal Pradesh using machine learning and AHP
Article Title: Landslide susceptibility mapping using machine learning models and analytical hierarchy process along NH-513, Pasighat to Yingkiong, Arunachal Pradesh, India
Article References: Adhyapok, M., & Dutta, M. K. (2026). Landslide susceptibility mapping using machine learning models and analytical hierarchy process along NH-513, Pasighat to Yingkiong, Arunachal Pradesh, India. Discover Geoscience, 4(1), Article 409. https://doi.org/10.1007/s44288-026-00781-2
Image Credits: AI Generated
DOI: 10.1007/s44288-026-00781-2
Keywords: landslide susceptibility, machine learning, Random Forest, artificial neural network, analytical hierarchy process, Arunachal Pradesh, Himalaya, NH-513, spatial block cross-validation, ROC-AUC, highway slope stability, GIS mapping
Cite Scienmag News
Blake Davidson. (October 28, 2026). Machine learning maps landslide danger along a Himalayan highway corridor. Scienmag. https://scienmag.com/machine-learning-maps-landslide-danger-along-a-himalayan-highway-corridor/
Blake Davidson. "Machine learning maps landslide danger along a Himalayan highway corridor." Scienmag, 28 October 2026, https://scienmag.com/machine-learning-maps-landslide-danger-along-a-himalayan-highway-corridor/. Accessed 2 November 2026.
Blake Davidson. "Machine learning maps landslide danger along a Himalayan highway corridor." Scienmag. October 28, 2026. https://scienmag.com/machine-learning-maps-landslide-danger-along-a-himalayan-highway-corridor/