Every time your smartphone recognizes a face, a smart camera detects motion, or a wearable filters out background noise, a specialized silicon engine called a neural processing unit springs into action. These chips are marvels of efficiency, but they share a hidden weakness that has quietly limited the battery life of edge devices for years: they are rigid. Most deep learning accelerators are hardwired to move data through the chip in one fixed pattern, no matter what the neural network actually demands. Now, a team of researchers at Intel’s Advanced Architecture Research group has unveiled FlexNPU, a Flexible Neural Processing Unit that throws away that rigidity entirely, reconfiguring its internal data plumbing layer by layer to squeeze out dramatic energy savings. The work, published in Frontiers in High Performance Computing, could reshape how AI chips are designed for the energy-starved world of edge computing.
To understand why FlexNPU matters, it helps to grasp a counterintuitive truth about AI hardware: the actual arithmetic is cheap. Multiplying and accumulating numbers inside a processing element costs remarkably little energy. What burns power is the movement of data. Shuttling activations and weights between DRAM, on-chip SRAM, and local register files can cost hundreds of times more energy per unit of data than the computation itself. The energy cost ratios used in the study tell the story starkly: a DRAM access costs roughly 200 times the energy of a processing element operation, and even an SRAM access costs six times as much. Because deep neural networks consist of tens to hundreds of layers, each with different tensor shapes and reuse preferences, the way data flows through the memory hierarchy determines the energy bill of every single layer.
Conventional accelerators have addressed this challenge by committing to one canonical dataflow strategy. Google’s TPU pioneered the weight stationary approach, holding weights in local buffers while streaming activations past them. MIT’s Eyeriss championed the row stationary dataflow, balancing reuse across inputs, weights, and partial sums. Other designs follow input stationary, output stationary, or non-local reuse patterns. Each strategy is optimal for a subset of network layers, but none is optimal for all of them. A fixed-schedule accelerator can only deliver peak data reuse and resource utilization for those layers whose characteristics happen to match its hardwired pattern. For everything else, the chip accepts suboptimal reuse, extra memory accesses, and wasted energy. FPGAs offer some flexibility, but once programmed, their configuration cannot change from one layer to the next during execution.
FlexNPU breaks this mold by adopting agile design principles. Instead of a fixed dataflow, the accelerator reads configurable software descriptors that tell it, for each layer, the optimal schedule: the loop ordering, blocking, and partitioning of the tensor operations. A cycle-accurate cost model evaluates candidate schedules and selects the one that minimizes latency and energy for each layer. The compiler can therefore configure the accelerator differently for a 1-by-1 convolution with 64 input channels and 256 output channels than for a depthwise layer with tiny channel counts and large spatial extents. The result is that data movement is optimized per layer for minimal transfer and energy consumption, a capability the researchers emphasize is unattainable in fixed dataflow architectures.
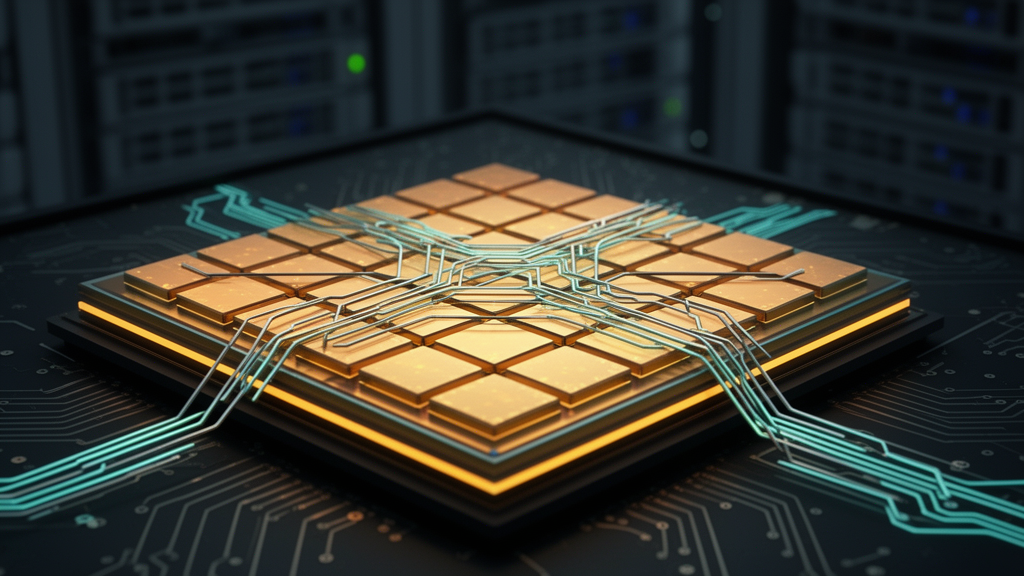
The heart of the machine is a 16-by-16 array of Versatile Processing Elements, each of which dynamically selects its compute template based on the optimal schedule. Each VPE contains register files for compressed input features, filter weights, and output partial sums, along with sparsity bitmap registers and a two-sided sparsity acceleration logic. The register files are split into sub-banks with multiple MAC units and multiplexers, allowing the PE to implement vector-vector, vector-matrix, or matrix-matrix templates depending on the layer’s optimal blocking factors. A flexible adder tree, called FlexTree, dynamically adapts its depth according to how input channels are partitioned across PEs, achieving partial sum accumulation speedups of up to 2.14 times over fixed tree architectures and up to 16 times across seven evaluated networks. A schedule-aware tensor distribution network handles the load and drain of data between SRAM and the PE array, rearranging layouts on the fly to match each layer’s reuse pattern.
FlexNPU’s second major innovation attacks the zeros. Deep neural networks are riddled with sparsity: ReLU activation functions zero out negative values, producing activation sparsity that can exceed 90 percent in deeper layers of networks like ResNet50 and MobileNetV2. Pruning techniques remove redundant weights, yielding weight sparsity levels of up to 90 percent. Quantization to INT8 or INT4 for edge inference adds further zeros. Existing sparse accelerators typically exploit only one side of this sparsity, skipping zero weights or zero activations but not both simultaneously. FlexNPU’s two-sided sparsity acceleration logic maintains both weights and activations in a zero-compressed format with sparsity bitmaps, merges the bitmaps to identify pairs where both operands are non-zero, and executes exactly one useful MAC operation per cycle, skipping ineffectual computations entirely. The compressed data flows through the entire memory hierarchy, reducing storage, bandwidth, and energy.
The experimental results are striking. Implemented in Chisel, synthesized on a 7-nanometer process node, and fabricated as a test chip in Intel’s 7-nanometer technology, FlexNPU operates at 2.4 gigahertz and 0.65 volts, delivering a dense peak performance of 7.37 TOPS with an efficiency of 5 TOPS per watt. Compared against Eyeriss and TPU under identical memory hierarchies, FlexNPU achieves up to 77 percent energy reduction for ResNet101 and YOLOv2, with average savings of 57 and 69 percent over Eyeriss and 14 and 22 percent over TPU. Across four sparse CNN benchmarks, FlexNPU delivers speedups of 1.8 to 3.3 times over dense accelerators and 1.7 to 2.0 times over weight-sparse designs, with energy efficiency improvements of 1.7 to 3.0 times. For transformer models including DETR-ResNet50, T5, MobileBERT, and DistilBERT, the accelerator provides 1.4 to 4.2 times speedup over dense baselines, with DistilBERT showing the highest gain of 4.15 times due to pronounced structured weight sparsity.
The implications extend beyond raw benchmark numbers. As AI workloads evolve at a breakneck pace, with new architectures emerging monthly and tensor dimensions in constant flux, hardware that is hardwired to one dataflow risks obsolescence. FlexNPU’s flexibility works seamlessly on top of existing performance features such as sparsity acceleration and low-precision logic, and the researchers note it does not diminish their impact. The flexibility does come at the cost of additional area overhead compared to fixed dataflow accelerators, but the energy savings on average across diverse network layers outweigh that penalty. The test chip measurements validate the design: the PE column is overwhelmingly dominated by the compute engine at 98 percent of power, confirming minimal overhead from control and data movement logic.
For the edge devices that populate our pockets, homes, and cities, FlexNPU represents a compelling vision: AI silicon that adapts itself to the workload rather than forcing the workload to adapt to the silicon. By treating dataflow as a software-configurable property rather than a hardware constant, and by exploiting sparsity on both sides of every multiplication, the design points toward a future where energy-efficient AI inference is not a compromise but a default. As neural networks continue to grow in complexity and diversity, accelerators like FlexNPU may well become the blueprint for the next generation of intelligent edge hardware.
Subject of Research: Computer Science
Article Title: FlexNPU: a dataflow-aware flexible deep learning accelerator for energy-efficient edge devices
Article References: Raha, A., Mathaikutty, D. A., Kundu, S., & Ghosh, S. K. (2025). FlexNPU: a dataflow-aware flexible deep learning accelerator for energy-efficient edge devices. Frontiers in High Performance Computing, 3, Article 1570210. https://doi.org/10.3389/fhpcp.2025.1570210
Image Credits: AI Generated
DOI: 10.3389/fhpcp.2025.1570210
Keywords: FlexNPU, deep learning accelerator, edge AI, energy efficiency, dataflow, sparsity acceleration, neural processing unit, Intel, dataflow-aware, flexible, deep, learning
Cite Scienmag News
Blake Davidson. (October 16, 2026). FlexNPU: The Shape-Shifting AI Chip That Rewires Itself Layer by Layer to Slash Energy Use. Scienmag. https://scienmag.com/flexnpu-the-shape-shifting-ai-chip-that-rewires-itself-layer-by-layer-to-slash-energy-use/
Blake Davidson. "FlexNPU: The Shape-Shifting AI Chip That Rewires Itself Layer by Layer to Slash Energy Use." Scienmag, 16 October 2026, https://scienmag.com/flexnpu-the-shape-shifting-ai-chip-that-rewires-itself-layer-by-layer-to-slash-energy-use/. Accessed 16 October 2026.
Blake Davidson. "FlexNPU: The Shape-Shifting AI Chip That Rewires Itself Layer by Layer to Slash Energy Use." Scienmag. October 16, 2026. https://scienmag.com/flexnpu-the-shape-shifting-ai-chip-that-rewires-itself-layer-by-layer-to-slash-energy-use/