

Depression has long been treated by medicine as a single diagnosis, yet clinicians and researchers have suspected for decades that the disorder is actually many conditions wearing the same label. A new study published in PLOS Digital Health lends computational muscle to that suspicion. A team led by Divya Sharma and Venkat Bhat developed a generative deep learning framework called SYNERGY-VAE, which sifts through enormous, multidomain health survey data to uncover hidden subgroups of the population with distinct health signatures and markedly different risks of depression. Working with data from the National Health and Nutrition Examination Survey, or NHANES, collected between 2005 and 2018, the researchers showed that the population naturally sorts into three latent clusters whose observed depression prevalence ranges from 6.8 percent to 10.9 percent, and that prediction models tailored to each cluster outperform models trained on everyone at once.
The scale and diversity of NHANES make it an ideal proving ground for this kind of analysis. The survey gathers information across demographic characteristics, dietary behavior, physical examination findings, laboratory measurements, and self-reported questionnaire responses. Historically, researchers studying depression risk have tended to analyze these domains separately, examining diet in one study, biomarkers in another, and psychosocial questionnaires in a third. That siloed approach, the authors argue, misses the integrated patterns that emerge when all the data streams are considered together. Depression, after all, is a complex and multifactorial disorder shaped by the interplay of biological, behavioral, and social determinants, and the interactions among those determinants may carry as much signal as any single variable.
SYNERGY-VAE addresses the integration problem with a variational autoencoder, a class of generative neural network that has become a workhorse of modern representation learning. In essence, a variational autoencoder compresses high-dimensional input data into a lower-dimensional latent space, a compact mathematical representation in which similar individuals end up close together. The architecture learns to encode the five NHANES modalities into this shared latent representation and then to decode it back, forcing the network to preserve the information that matters most for reconstructing each person’s complete health profile. Because the compression is probabilistic rather than deterministic, the model learns a smooth, structured space rather than a brittle lookup table, which makes it well suited to discovering natural groupings in messy population data.
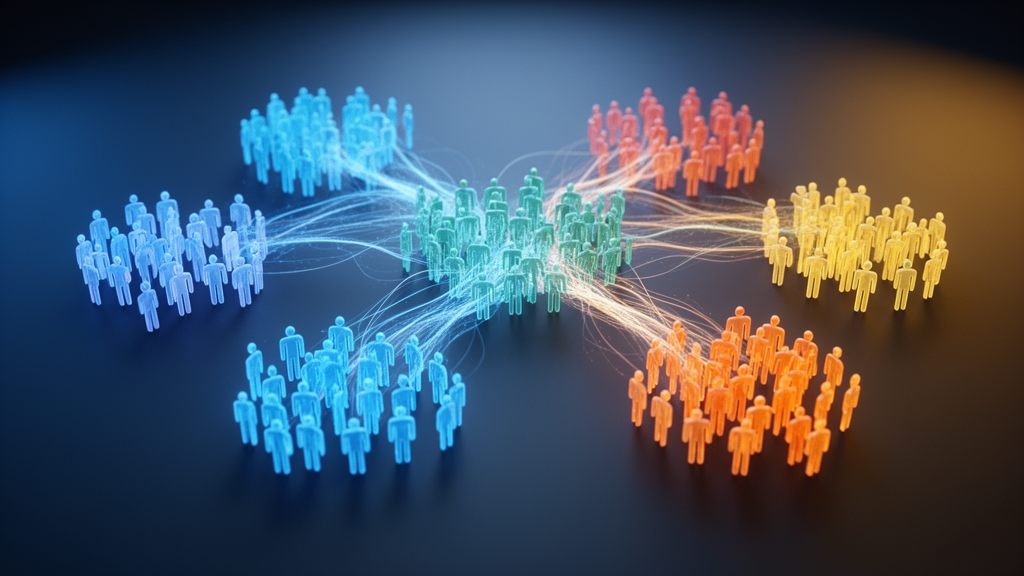
Once the latent space was learned, the team applied clustering within it and three distinct subpopulations emerged. Each cluster carried a recognizable health signature, a constellation of demographic, dietary, clinical, laboratory, and questionnaire characteristics that distinguished its members from the rest of the sample. Critically, the clusters were not merely statistical artifacts: they differed substantially in their observed depression prevalence, with rates spanning 6.8 percent to 10.9 percent across the analytic sample. That spread suggests the model was picking up genuine heterogeneity in depression risk, the kind of heterogeneity that a one-size-fits-all screening approach would smooth over entirely.
A persistent criticism of deep learning in medicine is that it functions as a black box, delivering predictions without explanations. The researchers confronted that challenge head-on by triangulating three complementary interpretability methods. First, they examined the encoder weights of the network itself, which reveal which input variables the model relies on most heavily when constructing the latent representation. Second, they computed standardized mean differences between clusters, a classical epidemiological measure that quantifies how far each cluster deviates from the overall population on every feature. Third, they applied permutation feature importance, or PFI, a technique that measures how much a model’s predictive performance degrades when a given feature is randomly shuffled; features whose shuffling causes the largest drop in performance are the ones the model truly depends on. By converging on the same signals from three independent directions, the analysis offers transparency that single-method interpretability studies often lack.
The interpretability work paid off in the next stage of the pipeline. Within each cluster, the team trained machine learning classifiers to predict depression risk, using the top 30 features ranked by permutation feature importance as model inputs. They evaluated performance using the area under the receiver operating characteristic curve, or AUC, in a 70/30 train-test split, a standard protocol for assessing how well a model generalizes to unseen data. The headline result is striking: cluster-specific models consistently surpassed pooled models trained on the entire sample, and the best performance came from an XGBoost model within Cluster 2, which achieved an AUC of 0.839 with a 95 percent confidence interval of 0.804 to 0.874. An AUC in that range indicates strong discriminative ability, meaning the model could reliably separate individuals at high risk of depression from those at lower risk within that subgroup.
Just as important as the performance gains was what the feature rankings revealed. The importance of individual predictors varied across clusters, indicating that each subgroup has its own unique depression risk profile. In other words, the variables that best forecast depression in one latent group are not necessarily the same variables that forecast it in another. This finding speaks directly to the central premise of precision mental health: that risk factors, and by extension screening strategies and interventions, should be tailored to the phenotype of the person in front of the clinician rather than to the average patient. A screening questionnaire tuned to the risk profile of one subgroup might overlook the most informative signals in another.
The implications extend beyond the specific dataset. Large health surveys like NHANES are conducted in many countries, and the framework developed here is, in principle, portable to any comparable multimodal data source. By integrating high-dimensional data across domains and making the subgroup discovery process transparent, SYNERGY-VAE offers a template for stratified, context-aware screening research. Instead of asking whether a single risk score works for everyone, researchers can ask which risk profiles exist in a population, how prevalent depression is within each, and which features carry predictive weight locally. That sequence, the authors suggest, could sharpen the design of future screening programs and contribute to the growing field of precision psychiatry.
The study also illustrates a broader shift in how machine learning is being applied to population health. Earlier generations of predictive models typically took a fixed feature set and a single outcome and asked how accurately the outcome could be forecast. Generative approaches like variational autoencoders invert that logic: they first learn the structure of the data itself, letting subgroups emerge from the geometry of the latent space, and only then build predictive models within each group. The combination of unsupervised structure discovery and supervised prediction, wrapped in an interpretability framework, reflects a maturing discipline that increasingly demands both accuracy and accountability from its algorithms.
Cautious interpretation remains warranted, as it does with any model trained on observational survey data. The clusters describe patterns in a specific cohort spanning 2005 to 2018, and the depression prevalence figures are observed rates within the analytic sample rather than causal estimates. The authors position SYNERGY-VAE as a tool to inform future screening research rather than a finished clinical instrument. Even so, the demonstration that a single national population contains latent subgroups with depression rates differing by more than four percentage points, and that subgroup-specific models predict risk more accurately than pooled ones, is a concrete step toward mental health care that recognizes the diversity hidden inside a single diagnostic label. If replicated and extended, frameworks of this kind could help ensure that the right questions are asked of the right people, at the right time, in the service of earlier and more equitable detection of depression.
Subject of Research: Explainable generative deep learning for discovering depression subgroups from multimodal population health survey data
Article Title: SYNERGY-VAE: An explainable generative deep learning framework for discovering depression subgroups from multimodal population health data
Article References: Sharma, D., Rueda, A., Lin, Q., Meshkat, S., Perivolaris, A., & Bhat, V. (2026). SYNERGY-VAE: An explainable generative deep learning framework for discovering depression subgroups from multimodal population health data. PLOS Digital Health, 5(9), e0001719. https://doi.org/10.1371/journal.pdig.0001719
Image Credits: AI Generated
DOI: 10.1371/journal.pdig.0001719
Keywords: depression, SYNERGY-VAE, variational autoencoder, NHANES, precision psychiatry, machine learning, clustering, interpretability, permutation feature importance, XGBoost, multimodal data, population health
Cite Scienmag News
Glenn Wilkins. (October 9, 2026). AI Finds Hidden Depression Subtypes in National Health Survey Data. Scienmag. https://scienmag.com/ai-finds-hidden-depression-subtypes-in-national-health-survey-data/
Glenn Wilkins. "AI Finds Hidden Depression Subtypes in National Health Survey Data." Scienmag, 9 October 2026, https://scienmag.com/ai-finds-hidden-depression-subtypes-in-national-health-survey-data/. Accessed 9 October 2026.
Glenn Wilkins. "AI Finds Hidden Depression Subtypes in National Health Survey Data." Scienmag. October 9, 2026. https://scienmag.com/ai-finds-hidden-depression-subtypes-in-national-health-survey-data/


