

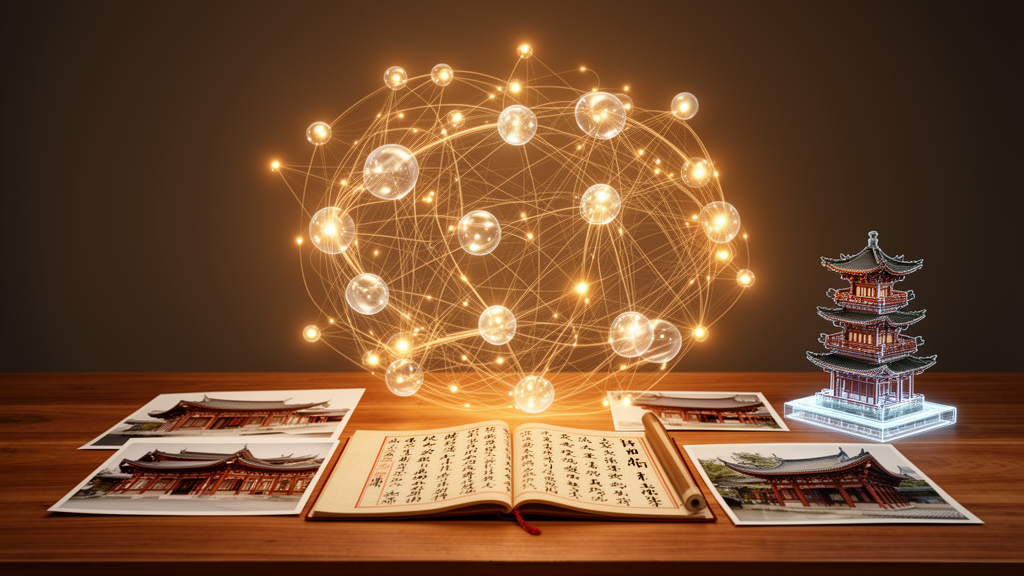
For centuries, the wooden temples, palaces and pavilions of China have been documented in fragments. A Song dynasty treatise describes a bracket set in classical prose; a surveyor’s photograph captures a weathered beam; a heritage information model renders the same component in precise three-dimensional geometry. Each source holds part of the truth, but they rarely speak to one another. A new study published in npj Heritage Science by researchers at Shanghai Jiao Tong University proposes a way to make them converse: a multimodal knowledge graph that binds text, images and 3D building components into a single, searchable web of knowledge for Chinese architectural heritage.
The framework, called ChAHMKG, short for Chinese Architectural Heritage Multimodal Knowledge Graph, rests on a carefully constructed ontological foundation the authors name YingzaoOnto. The name is a nod to Yingzao Fashi, the twelfth-century state building manual attributed to Li Jie under the Song dynasty, and to Gongcheng Zuofa Zeli, the Qing dynasty counterpart that codified workshop practices centuries later. Rather than treating these treatises as mere historical curiosities, the team mined them for their structured vocabulary of building types, components, materials and construction rules, then merged that vocabulary with existing heritage and spatial ontologies to create an interoperable schema. The result is a formal language in which a dougong bracket, a photograph of one, a paragraph describing one, and a voxelized 3D model of one can all be described in compatible terms.
The technical heart of the paper is what the authors call the Semantic-Geometric Alignment module. The problem it solves is familiar to anyone who has worked with modern artificial intelligence: text, images and 3D geometry live in fundamentally different mathematical spaces. A sentence is a sequence of tokens, an image is a grid of pixels, and a building information model is a set of parametric solids. A neural network trained on one modality understands nothing about the others. The alignment module tackles this by projecting features from all three modalities into a shared embedding space, where a description of a component and the correct 3D model of that component end up close together, while mismatched pairs are pushed far apart.
The mechanism for achieving this is contrastive learning, a technique that has powered recent breakthroughs in image-text models. During training, the system is shown matched triples of text, image and HBIM-derived features, which serve as positive examples, alongside deliberately mismatched combinations drawn through positive-negative sampling. The network learns to pull genuine matches toward one another in the embedding space and to repel false pairings. Crucially, the researchers add something most generic multimodal models lack: ontology-guided geometric constraints. Because YingzaoOnto encodes how components relate hierarchically and spatially, for instance which members sit above or below others in a timber frame, the training process can penalize embeddings that violate these known structural relationships. Domain knowledge thus acts as a scaffold for machine learning rather than being ignored by it.
To train and evaluate the system, the team curated a dataset spanning all three modalities, drawing on historical texts, field photographs and HBIM geometry of traditional Chinese buildings. Heritage BIM, or HBIM, is an adaptation of the building information modeling standard used in construction, retooled for historic structures where components are irregular, hand-crafted and often poorly documented. Voxelizing the HBIM geometry, that is, converting smooth solids into regular three-dimensional grids, gives the neural network a uniform input format it can process alongside images and text. The experiments reported in the paper show that this tri-modal training improves cross-modal retrieval, meaning the system can, for example, take a photograph of an unidentified bracket set and surface the relevant treatise passage and matching 3D component.
Two further capabilities stand out. The first is HBIM semantic enrichment: the graph can attach ontological labels and textual knowledge to geometric elements that were previously bare shapes, turning a dumb model of a beam into a model that knows it is a specific class of beam with documented proportions and historical context. The second is period-matched modular rule validation. Because Chinese timber construction was governed by modular systems, with component dimensions derived from standardized units that changed between the Song and Qing eras, the system can check whether the geometry in a model actually conforms to the rules of the period it claims to belong to. A component whose proportions contradict the Yingzao Fashi module system can be flagged automatically, offering conservators a computational check on dating and authenticity.
The practical implications reach into every stage of conservation practice. Documentation teams could query the graph in natural language and receive evidence spanning centuries of textual tradition and modern survey data. Restoration planners could use the geometric checking functions to verify that proposed interventions respect historical modular rules before a single timber is cut. Because every link in the graph is traceable, connecting a claim back to its source text, photograph or model, the infrastructure supports evidence-based restoration rather than intuition-driven reconstruction. In a field where a single wrong assumption about a component’s original form can be physically carved into a protected monument, that traceability is not a luxury but a safeguard.
The research also speaks to a broader trend in digital humanities and cultural informatics: the move from isolated digital archives to semantically integrated knowledge infrastructures. Museums, heritage agencies and research groups have digitized enormous quantities of material over the past two decades, but digitization alone does not create understanding. Knowledge graphs provide the connective tissue, and multimodal alignment extends that tissue across the sensory divide between what is written, what is seen and what is measured. The Shanghai Jiao Tong team’s contribution is to demonstrate that this integration can respect the deep domain structure of a specific craft tradition rather than flattening it into generic categories.
Methodologically, the work illustrates how classical texts can serve as computational resources. Yingzao Fashi and Gongcheng Zuofa Zeli were written as operational manuals, with systematic terminology and rule-based prescriptions, which makes them unusually amenable to ontological formalization. By grounding the knowledge graph in these sources, the researchers ensure that the machine’s vocabulary matches the vocabulary of the tradition itself, an alignment of a different kind but one just as important as the embedding-space alignment at the core of the model. The ontology thereby becomes a bridge between twelfth-century scholarship and twenty-first-century artificial intelligence.
The study, which was supported by Shanghai Jiao Tong University programs and carried out in part using Huawei’s Ascend AI technology stack, arrives as heritage professionals worldwide grapple with aging monuments, shrinking craft expertise and climate-driven deterioration. Tools that can consolidate scattered evidence, validate it against historical rules and make it retrievable across modalities offer a way to preserve not just the stones and timbers but the knowledge of how they fit together. The authors position ChAHMKG as a foundation for conservation documentation, geometric checking and evidence-based restoration, and the framework’s open, ontological design suggests it could be extended to other building traditions beyond China. For a discipline that has always depended on the careful transmission of knowledge from master to apprentice, the prospect of a machine-readable, multimodal memory of that knowledge marks a quiet but consequential turning point.
Subject of Research: A multimodal knowledge graph aligning text, images and 3D HBIM models for Chinese architectural heritage conservation
Article Title: Multimodal knowledge graph for Chinese architectural heritage based on semantic-geometric alignment
Article References: Cao, Y., Zuo, Z., Xu, G., & Zhang, Q. (2026). Multimodal knowledge graph for Chinese architectural heritage based on semantic-geometric alignment. npj Heritage Science. https://doi.org/10.1038/s40494-026-03038-w
Image Credits: AI Generated
DOI: 10.1038/s40494-026-03038-w
Keywords: knowledge graph, Chinese architectural heritage, multimodal alignment, contrastive learning, HBIM, Yingzao Fashi, ontology, heritage conservation, 3D modeling, cross-modal retrieval, semantic enrichment, digital humanities
Cite Scienmag News
Courtney Benton. (October 9, 2026). AI Knowledge Graph Links Ancient Chinese Building Texts, Photos and 3D Models. Scienmag. https://scienmag.com/ai-knowledge-graph-links-ancient-chinese-building-texts-photos-and-3d-models/
Courtney Benton. "AI Knowledge Graph Links Ancient Chinese Building Texts, Photos and 3D Models." Scienmag, 9 October 2026, https://scienmag.com/ai-knowledge-graph-links-ancient-chinese-building-texts-photos-and-3d-models/. Accessed 9 October 2026.
Courtney Benton. "AI Knowledge Graph Links Ancient Chinese Building Texts, Photos and 3D Models." Scienmag. October 9, 2026. https://scienmag.com/ai-knowledge-graph-links-ancient-chinese-building-texts-photos-and-3d-models/


