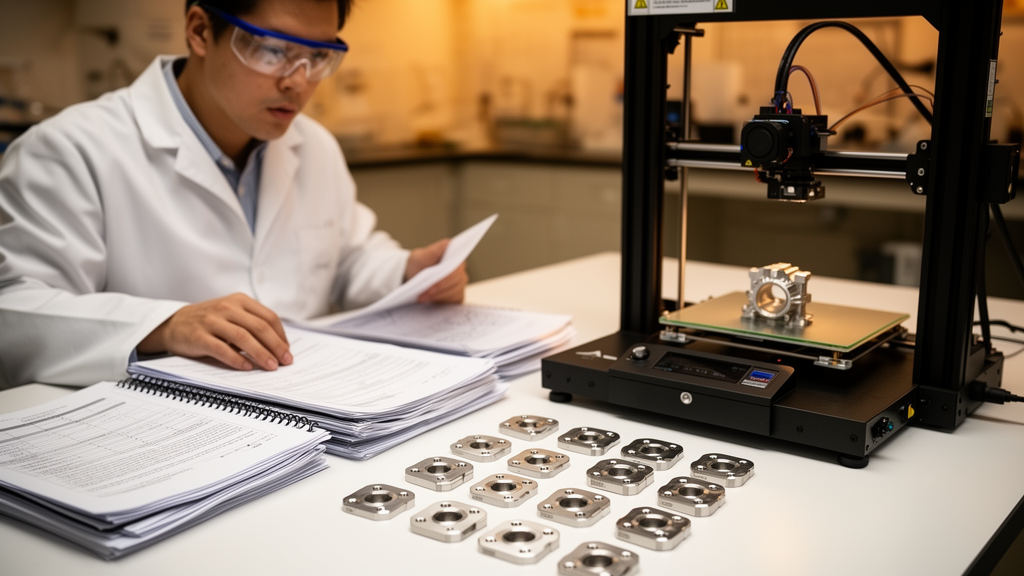
Titanium parts built by additive manufacturing are moving from prototype to production, and their most safety-critical property is fatigue life. Yet the data needed to predict it remain scattered across decades of unrelated studies. A team at Penn State and NIST has now tackled the messy job of aggregating archival fatigue data for additively manufactured Ti-6Al-4V, exposing why simply pooling numbers from old papers produces unreliable answers — and how to fix it.
The work, published in the Journal of Materials Science by I. J. Wietecha-Reiman, X. Zhao and T. A. Palmer, addresses a problem familiar to anyone who has tried meta-analysis in materials science: the raw stress amplitude and cycles-to-failure values are only half the story. Each data point is meaningful only alongside its metadata — the alloy chemistry, powder characteristics, machine type, scan strategy, heat treatment, surface finish, specimen geometry and testing procedure. Capturing those variables is what allows larger trends and sources of scatter to be identified across a combined dataset.
The authors found that existing practices for handling such metadata are riddled with recording and structural errors. Values are reported inconsistently, units drift between studies, and entire fields are missing. These gaps limit traditional statistical analysis and will also undermine the high-fidelity application of emerging machine learning and large language model tools, which are only as good as the completeness and consistency of the data they are trained on.
To maximize usable data, the researchers developed formalized procedures for compiling datasets from independent studies. Where metadata values are unreported but meet specific criteria, they are replaced with reasonable estimates through a systematic imputation process. The approach draws on established statistical thinking about missing data — including the principle that the proportion of missing data alone should not dictate imputation decisions — and is documented in a set of suggested imputation rules published with the paper.
Building on an existing aggregated dataset, the team also proposes a structured method for introducing new studies seamlessly, so the database can keep growing without re-engineering. The contents are released as de-normalized CSV files with a data dictionary and an alphabetized source list, allowing researchers to restructure them for any database management system.
The technical payoff is a single large dataset in which sources of uncertainty and scatter in fatigue life can be systematically identified. Because the metadata are more general than the correlative information in databases used to develop design allowables — such as MMPDS — they cannot replace them, but they are still valuable for revealing how processing choices propagate into fatigue performance.
The authors argue the database can serve as a reliable benchmark for evaluating whether new machine learning and LLM tools genuinely add value. With hallucination in large language models an active concern, and interpretability still contested, having a curated ground truth against which tools can be tested is a rare asset in materials informatics.
The effort was supported by the Navy SBIR/STTR program and the American Welding Society Graduate Research Fellowship. For a field where fatigue data from additive manufacturing are often criticized for poor applicability and unquantified uncertainty, this work offers something concrete: not a new alloy or a clever model, but the unglamorous data engineering that makes both possible.
The choice of Ti-6Al-4V as the focal alloy is not incidental. It is the most widely characterized titanium alloy in additive manufacturing, appearing in aerospace brackets, structural fittings, and biomedical implants, and it exhibits a fatigue behavior that is unusually sensitive to processing history. Defects such as lack-of-fusion voids, keyhole porosity, and gas entrapment act as crack initiation sites, while surface roughness from as-built conditions can dominate life at low stress amplitudes. Post-processing steps like hot isostatic pressing close internal porosity and can shift fatigue lives by orders of magnitude, but only if the treatment temperature and pressure are recorded. When a metadata field for HIP conditions is blank or ambiguous, the aggregated data points become effectively uninterpretable, which is precisely the kind of structural error the new compilation procedures are designed to catch.
The distinction between stress-controlled and strain-controlled testing matters here as well. The archival literature on additively manufactured Ti-6Al-4V is dominated by stress-life testing, in which specimens are cycled at a fixed stress amplitude until failure or runout. This format lends itself to aggregation because the two primary variables — stress amplitude and cycles to failure — are directly comparable across laboratories. But the comparability is superficial. Load ratio, frequency, waveform shape, specimen orientation relative to the build direction, and gauge section preparation all modulate the measured life, and each of these must be captured as metadata for the pooled dataset to support meaningful statistical inference. The authors’ insistence on recording testing procedures alongside the mechanical data reflects this reality.
Imputation deserves closer scrutiny because it is the most consequential and most controversial step in the workflow. Replacing an unreported value with a reasonable estimate is defensible when the missing value is strongly constrained by context — for example, if a study states that specimens were machined and polished, the surface roughness can be bounded within a narrow range. It becomes hazardous when the missing value is weakly constrained, such as an unspecified powder particle size distribution or an unreported layer thickness. The criteria the authors apply determine which gaps can be safely filled and which must remain flagged as unknown. This is a deliberate departure from naive approaches that impute everything with column means or medians, which would wash out the very processing variability the database is meant to expose.
The de-normalized CSV format chosen for release is itself a meaningful decision. Normalized relational databases enforce schema constraints that prevent many recording errors but require expertise to query and restructure. De-normalized flat files trade some of that protection for accessibility, allowing researchers in materials departments without database infrastructure to begin analysis immediately. The accompanying data dictionary mitigates the risk by defining each field explicitly, and the alphabetized source list preserves provenance so that any individual record can be traced back to its original publication. This provenance chain is what enables the structured ingestion of new datasets: a contributor can map their study’s fields onto the existing schema rather than inventing new column names that fragment the database.
The benchmarking role the authors envision for the database addresses a growing tension in materials informatics. Machine learning models trained on aggregated mechanical data can interpolate within the training distribution but often fail when asked about processing combinations that are underrepresented. Large language models introduce a different failure mode: they can generate plausible-sounding but fabricated property values, and without a curated ground truth there is no systematic way to measure how often this occurs. A dataset with documented imputation decisions, explicit provenance, and known metadata completeness provides exactly the reference needed to quantify both interpolation error and hallucination rate. The authors position the database not as a finished product but as living infrastructure against which emerging tools can be evaluated as they mature.
The broader context of archival data aggregation in materials science is worth noting. Previous efforts — the NIMS fatigue data sheets for conventional alloys, the composite material fatigue databases maintained for wind energy applications, and the subsea industry steel fatigue compilations — demonstrated that pooled archival data can support design decisions when metadata are handled rigorously. The MMPDS handbook represents the industrial endpoint of this philosophy, where correlative information is dense enough to support statistically derived design allowables. What distinguishes the present work is its target: not design allowables but the identification of uncertainty sources and the evaluation of computational tools. This allows the metadata to remain more general, capturing processing context without requiring the exhaustive correlative detail that MMPDS certification demands.
The funding sources behind the effort — the Navy SBIR/STTR program and the American Welding Society Graduate Research Fellowship — reflect the dual interest in this problem. Naval applications drive demand for qualified additive manufacturing of titanium structural components, where fatigue certification remains a bottleneck. The welding and materials joining community brings expertise in melt pool physics and process control that directly informs how processing metadata should be structured. That a graduate fellowship supported the work underscores the data engineering labor involved: digitizing figures from published papers, extracting values with tools like WebPlotDigitizer, reconciling unit inconsistencies, and documenting every decision in a form that others can audit.
Looking forward, the structured ingestion procedure the authors propose could become a template for other alloy systems and other mechanical properties. The same recording and structural errors they document in Ti-6Al-4V fatigue data almost certainly afflict archival datasets for additively manufactured steels, nickel superalloys, and aluminum alloys, where related work by the same group on austenitic stainless steel fatigue suggests the methodology is transferable. As additive manufacturing moves into certified production of flight-critical and implant-critical components, the ability to pool and curate historical data — rather than generating everything anew — will determine how quickly the field can close the gap between process qualification and reliable life prediction. The unglamorous work of data curation, this paper argues, is where that closure begins.
Subject of Research: Addressing limitations in the aggregation of archival fatigue data for an additively manufactured titanium alloy
Article Title: Addressing limitations in the aggregation of archival fatigue data for an additively manufactured titanium alloy
Article References: Wietecha-Reiman, I. J., Zhao, X., & Palmer, T. A. (2026). Addressing limitations in the aggregation of archival fatigue data for an additively manufactured titanium alloy. Journal of Materials Science. https://doi.org/10.1007/s10853-026-13789-3
Image Credits: AI Generated
DOI: 10.1007/s10853-026-13789-3
Keywords: Addressing, limitations, aggregation, archival, fatigue, data, additively, manufactured, titanium, alloy, scientific research
Cite Scienmag News
Denise Maddox. (October 17, 2026). Rescuing decades of scattered fatigue data for 3D-printed titanium. Scienmag. https://scienmag.com/rescuing-decades-of-scattered-fatigue-data-for-3d-printed-titanium/
Denise Maddox. "Rescuing decades of scattered fatigue data for 3D-printed titanium." Scienmag, 17 October 2026, https://scienmag.com/rescuing-decades-of-scattered-fatigue-data-for-3d-printed-titanium/. Accessed 17 October 2026.
Denise Maddox. "Rescuing decades of scattered fatigue data for 3D-printed titanium." Scienmag. October 17, 2026. https://scienmag.com/rescuing-decades-of-scattered-fatigue-data-for-3d-printed-titanium/