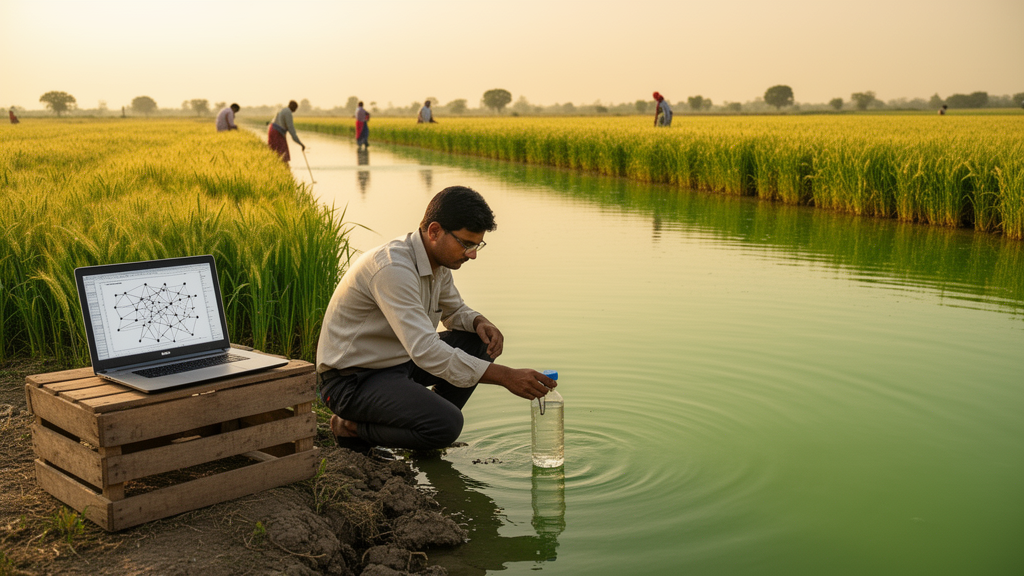
Two Himalayan glacier-fed rivers in Indian Punjab, the Satluj and the Beas, have been the subject of a sixteen-year effort to model drinking water quality using machine learning rather than the traditional, step-by-step index calculations that water managers normally rely on. A new study published in Discover Water shows that a Random Forest regression model could predict the Canadian Council of Ministers of the Environment water quality index (CCME WQI) with a coefficient of determination of 0.97 on test data, while a multiple linear regression model reached only 0.64 on the full dataset. The finding suggests that non-linear, data-driven frameworks may offer a faster and more flexible alternative to conventional index computation for monitoring river health.
Sampling followed a uniform monitoring protocol at quarterly and monthly intervals across 24 locations: nine on the Beas, eleven on the Satluj, and four at the confluence of the two rivers. The resulting datasets were substantial, comprising 2,280 observations for the full river network, 844 for the Beas, 1,038 for the Satluj, and 373 for the post-confluence stretch.
In this study, the index was built from four parameters that India’s Central Pollution Control Board designates as key to defining drinking water suitability: dissolved oxygen, biological oxygen demand, total coliform bacteria, and pH. While well established, the index calculation is time consuming and tied to a fixed set of variables, which the authors argue is increasingly unreliable under rapid environmental and anthropogenic change.
To wrap predictive models around the index, the researchers first reduced the pool of candidate variables from thirty to a manageable set. For the linear models, they standardized and normalized the data, checked for multicollinearity using variance inflation factors, and dropped any variable with a VIF of ten or greater. Stepwise regression was then bootstrapped one hundred times, with variables retained only if they were selected in more than seventy of the hundred bootstrap samples. This procedure identified ten variables for the full dataset, five for the Beas, and four each for the Satluj and confluence datasets, with non-significant predictors removed at a p-value threshold of 0.05.
For the non-linear approach, Random Forest regression was chosen precisely because it tolerates non-normal, collinear data and complex interactions among many predictors. Each of the 500 trees was trained on a bootstrap sample of roughly two-thirds of the training data, and variable importance was assessed through permutation importance on out-of-bag samples. Variables were retained if permuting them increased the mean squared error by more than five percent. This yielded seven variables each for the full, Beas, and Satluj datasets, but only two, biological oxygen demand and total coliform, for the confluence dataset, which the authors therefore reserved as an independent test set.
The results were striking. Random Forest models explained nearly 99 percent of the variance in the water quality index for the full and Satluj datasets and 94 percent for the Beas dataset, all evaluated on held-out test portions. The linear models, by contrast, achieved adjusted R-squared values of roughly 0.62 on the full data, 0.72 for the Beas, and 0.70 for the Satluj, with test-set performance of about 0.69 for the river-specific models and 0.60 for the full model. The confluence-based linear model failed entirely, producing predictions outside the valid 0 to 100 index range and an efficiency below zero, likely because of its small sample size of 373 observations.
Beyond raw predictive power, the modeling exercise reshaped the picture of which variables matter. Dissolved oxygen, biological oxygen demand, and total coliform emerged as important across the datasets, confirming their central role in the river network’s biogeochemistry. But the analysis also flagged fecal coliform, total dissolved solids, ammoniacal nitrogen, phosphate, chemical oxygen demand, and other parameters that do not enter the standard index calculation. Notably, pH, which the Central Pollution Control Board includes among its four designated parameters, was not identified as an important predictor by either the stepwise regression or the Random Forest importance ranking.
The underlying pollution picture is sobering. Fecal coliform exceeded acceptable limits at multiple locations on both rivers and at the confluence, indicating waters unsuitable for drinking. At heavily polluted sites on the Satluj, including the Buddha Nullah and Dharamkot, chemical oxygen demand exceeded 250 milligrams per liter. Ammoniacal nitrogen reached up to 30 milligrams per liter and phosphates 6.4 milligrams per liter in Satluj samples, traced to municipal and industrial effluent discharge and agricultural runoff. Total dissolved solids exceeded 1,000 milligrams per liter at certain Satluj locations, attributed mainly to dyeing and textile industries near Ludhiana and Jalandhar.
The authors are candid about the limitations of their work. The dataset was not split into pre-monsoon, monsoon, and post-monsoon seasons, and random train-test splitting can risk information leakage and inflated performance estimates. However, they note that models built on the Satluj and Beas data were also tested against the after-confluence dataset, a genuinely independent set with different characteristics, where performance declined but remained comparable. The models are valid only within the boundary conditions of the training data, and their performance beyond that range could change with shifts in river hydrology, though continuous data feeds could help maintain accuracy.
The broader implication is a shift from static index computation toward predictive, data-driven monitoring. Because the Random Forest framework can associate index information with the full spectrum of measured parameters and capture non-linear relationships that linear regression cannot, the authors propose it as a transferable model for the entire Satluj-Beas network. With continuous data input, such frameworks could enable automatic updates of water quality variables and pollutant loads, supporting real-time monitoring, the design of water treatment strategies tailored to different river stretches, and the implementation of sustainable water policies across the Indus basin.
Subject of Research: Machine learning prediction of drinking water quality index for two Indus basin rivers in Indian Punjab
Article Title: Potability assessment of surface water of two Indus basin rivers using information enhanced linear and non-linear data-driven frameworks
Article References: Kaur, H., Benbi, D. K., Chandel, S., Kaur, M., Singh, D., & Singh, K. (2026). Potability assessment of surface water of two Indus basin rivers using information enhanced linear and non-linear data-driven frameworks. Discover Water, 6(1), Article 139. https://doi.org/10.1007/s43832-026-00474-4
Image Credits: AI Generated
DOI: 10.1007/s43832-026-00474-4
Keywords: water quality index, Random Forest, multiple linear regression, Satluj river, Beas river, Indian Punjab, CCME WQI, river pollution, machine learning, Punjab Pollution Control Board, drinking water, Indus basin
Cite Scienmag News
Violet Maxwell. (October 27, 2026). Random Forest Outperforms Regression in Predicting River Water Quality in Indian Punjab. Scienmag. https://scienmag.com/random-forest-outperforms-regression-in-predicting-river-water-quality-in-indian-punjab/
Violet Maxwell. "Random Forest Outperforms Regression in Predicting River Water Quality in Indian Punjab." Scienmag, 27 October 2026, https://scienmag.com/random-forest-outperforms-regression-in-predicting-river-water-quality-in-indian-punjab/. Accessed 28 October 2026.
Violet Maxwell. "Random Forest Outperforms Regression in Predicting River Water Quality in Indian Punjab." Scienmag. October 27, 2026. https://scienmag.com/random-forest-outperforms-regression-in-predicting-river-water-quality-in-indian-punjab/