

…
The publication of MultimerMapper arrives at a moment when the bottleneck in computational structural biology has visibly shifted. Producing a single high-quality structural model of a protein complex is no longer the limiting step; the limiting step is deciding what to model in the first place and how to interpret the growing piles of predictions that modern servers can generate in an afternoon. When AlphaFold2-multimer and, more recently, AlphaFold3 became available through public and cloud-based servers, individual laboratories gained the ability to submit dozens or hundreds of chain combinations without owning specialized hardware. The authors of the new study experienced this firsthand while working on trypanosomatid proteins, organisms that include the parasites responsible for Chagas disease, leishmaniasis, and African sleeping sickness. Their initial goal was straightforward: predict the structures of poorly characterized complexes to guide experiments at the bench. What they encountered instead was a combinatorial explosion of possible assemblies, ambiguous interaction signals, and models whose apparent interfaces changed depending on which other proteins were included in the same prediction job.
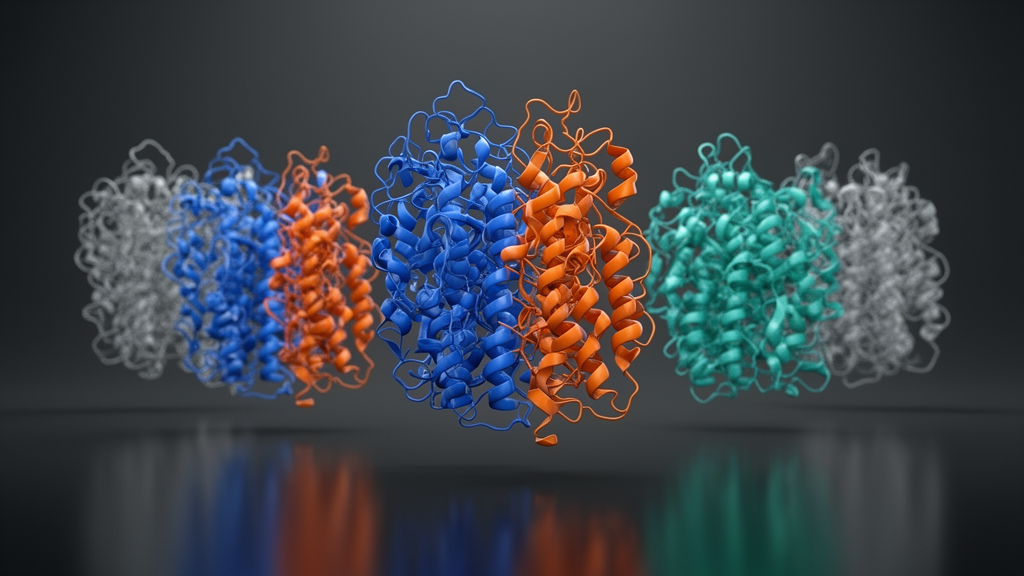
That last observation, that a predicted interface is not a fixed property of two sequences but can depend on the composition of the entire prediction, forms the conceptual core of the work. The phenomenon has a plausible mechanistic basis. Protein surfaces are finite, and many proteins carry multiple binding patches that can each accommodate different partners. When a structure prediction model is asked to place three or more chains in a single coordinate file, the network optimization underlying the prediction must negotiate which contacts to realize. A surface occupied by protein A in one prediction may instead engage protein B in another, and a conformational shift visible in one compositional context may be absent in a second. Competitive binding scenarios, in which two proteins target the same or overlapping sites, make certain predicted assemblies mutually exclusive in a physical sense, yet standard analysis workflows treat every output model as an independent, equally interpretable snapshot. MultimerMapper formalizes the comparison across these snapshots, asking statistically which interfaces and conformational states recur, which appear only when a particular partner is present, and which vanish when a competitor is introduced.
The methodological machinery behind this comparison draws on several established quantitative signals that practicing structural biologists will recognize. Each prediction run produces not only atomic coordinates but also per-residue confidence values in the form of pLDDT scores and a predicted aligned error matrix, or PAE, describing the expected positional uncertainty between every pair of residues. Inter-chain regions of the PAE matrix carry information about how confidently the model places two chains relative to one another, and the authors extract the minimum inter-chain PAE value, abbreviated miPAE, for every decomposed chain pair within every model. They complement this with the predicted docking confidence score, pDockQ, which was developed specifically to discriminate genuine protein-protein contacts from incidental proximity in predicted assemblies. By decomposing each multi-chain model into all possible chain pairs and recording these metrics in tabular form, the pipeline converts a coordinate ensemble into a structured dataset amenable to classical statistical and graph-theoretic analysis, a deliberate departure from approaches that rely on additional AI machinery to interpret AI output.
The choice of validation background deserves attention because it stresses the method in a way that familiar model organisms would not. Trypanosomatids diverged from the main eukaryotic lineage very early and their proteins show low sequence identity to well-annotated counterparts in yeast, flies, or humans, which degrades the quality of the multiple sequence alignments that feed structure prediction models. At the same time, core eukaryotic complexes retain recognizable structural features across this evolutionary distance. A pipeline that infers stoichiometries and interfaces reliably under these degraded-alignment conditions gains credibility that a validation restricted to well-sampled human complexes could not provide. The authors also tailored their alignment strategy for this work, modifying the Discoba sequence database to improve matching within the trypanosomatid taxonomic group and concatenating the resulting alignments with those from the standard ColabFold MSA server, a procedure described in detail in the article’s supplementary material along with its measurable effects on model confidence metrics.
Computational cost is a practical dimension that the article addresses through its infrastructure choices. The local AlphaFold2-multimer runs were executed on Amazon Web Services instances of varying sizes, from g4dn and g5 GPU families to p3-class instances, selected according to dataset size and the total residue count of each prediction. Each protein combination generated five models with up to twenty recycling iterations, with early stopping when two successive models converged within a root-mean-square-deviation threshold of half an angstrom. These settings matter to readers planning their own analyses because recycling behavior and model count directly influence both the confidence metrics extracted downstream and the expense of sampling the stoichiometric space. The stoichiometric space exploration algorithm at the heart of MultimerMapper is designed to make this sampling informative rather than exhaustive, guiding users toward the chain combinations most likely to resolve assembly ambiguity, an important consideration when a system of even modest size can admit an impractically large number of candidate compositions.
For researchers in structural biology and bioinformatics, the study suggests a workflow in which structure prediction is treated as ensemble generation rather than model production. The overlapping predictions that arise naturally when exploring a complex of unknown composition, the same overlapping subcomplex strategy that inspired the combinatorial assembly approach of CombFold, become the raw material for context-dependent analysis. Where CombFold assembles these fragments into large static models, often requiring prior stoichiometric knowledge, MultimerMapper instead interrogates the variability among them, inferring stoichiometric coefficients when no experimental data or templates are available and flagging alternative interaction modes statistically associated with specific partner compositions. The distinction is consequential for the field because stoichiometry inference from sequence data alone remains an unsolved problem, and dynamic or transient interactions, which cause proteins to associate and dissociate in a time- and context-dependent manner, systematically confound any analysis that assumes a single fixed assembly.
Several caveats frame the appropriate use of these tools. Structure prediction models, by themselves, still fall short of capturing the full dynamic nature of protein interactions and conformational diversity, and the statistical associations that MultimerMapper reports are hypotheses about interaction behavior rather than experimental measurements. A predicted interface that appears only in the presence of a particular partner may reflect genuine allosteric or compositional dependence, or it may reflect artifacts of the prediction process under low-alignment-quality conditions. The authors’ own testing on non-trypanosomatid complexes produced quantitative evidence of general applicability while explicitly delineating strengths and areas for improvement, an honest accounting that readers should weigh when planning applications to their own systems. The pipeline’s value is greatest for large unknown complexes, competitive binding scenarios, and conformational changes that would otherwise render interpretation of a handful of models ambiguous, and it is positioned as a complement to, not a replacement for, experimental determination of assembly stoichiometry and dynamics.
The broader significance for the bioinformatics community lies in the demonstration that non-AI analytical tooling has a productive role alongside the generative models that dominate the field. Statistics, graph theory, and purpose-built algorithms applied to the confidence signals already embedded in prediction outputs can extract biological information that the models themselves do not explicitly report, including higher-order subassemblies, alternative interaction modes, and conformational states tied to partner composition. As prediction servers continue to broaden access and as successive model generations extend coverage beyond polypeptides to nucleic acids and other molecules, the volume of overlapping prediction data available to individual laboratories will only grow. Tools that systematically sample, integrate, and visualize this data, supporting the exploration of functional mechanisms and assembly paths, address a gap that the authors identify as common to the field, particularly for highly dynamic complexes with unknown stoichiometries, and their work offers a template for how such analysis might be extended to other prediction systems and molecular types in future iterations.
Subject of Research: Context-dependent protein structure prediction analysis and complex stoichiometry inference with MultimerMapper
Article Title: Context-dependent protein structure prediction analysis and complex stoichiometry inference with MultimerMapper
Article References: Rodríguez Araya, E., & Serra, E. (2026). Context-dependent protein structure prediction analysis and complex stoichiometry inference with MultimerMapper. Frontiers in Bioinformatics, 6, Article 1914731. https://doi.org/10.3389/fbinf.2026.1914731
Image Credits: AI Generated
DOI: 10.3389/fbinf.2026.1914731
Keywords: Context-dependent, protein, structure, prediction, analysis, complex, stoichiometry, inference, MultimerMapper, scientific research
Cite Scienmag News
Jason Bradley. (October 17, 2026). MultimerMapper maps the hidden dynamics of AlphaFold protein complexes. Scienmag. https://scienmag.com/multimermapper-maps-the-hidden-dynamics-of-alphafold-protein-complexes/
Jason Bradley. "MultimerMapper maps the hidden dynamics of AlphaFold protein complexes." Scienmag, 17 October 2026, https://scienmag.com/multimermapper-maps-the-hidden-dynamics-of-alphafold-protein-complexes/. Accessed 17 October 2026.
Jason Bradley. "MultimerMapper maps the hidden dynamics of AlphaFold protein complexes." Scienmag. October 17, 2026. https://scienmag.com/multimermapper-maps-the-hidden-dynamics-of-alphafold-protein-complexes/


