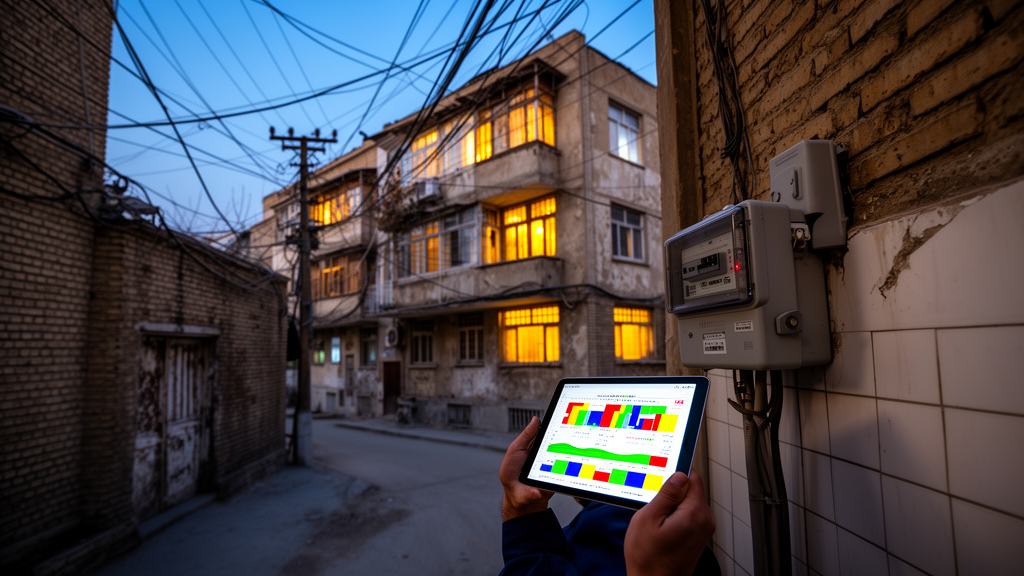
In one of Tehran’s oldest and most crowded municipal districts, researchers have tested whether machine-learning algorithms can untangle the web of factors that drive household water, electricity, and gas consumption. The study, published in the journal City and Built Environment, focused on District 10 of Tehran Municipality, a compact inner-city area of roughly 807 hectares that is home to about 304,000 residents, giving it one of the highest population densities in the Iranian capital at around 420 persons per hectare. Its neighborhood fabric dates largely from 1925 to 1975, and the district is characterized by worn-out building stock, high density, and a shortage of green space. The authors, Ali Shamaei and Kamran Jafarpour Ghalehteimouri, set out to model residential resource consumption in this deteriorated urban fabric and to identify which building-level characteristics matter most, with the broader aim of informing energy-efficient urban regeneration.
The research team assembled its dataset from utility records and field surveys collected throughout the calendar year 2023, ensuring coverage of heating, cooling, and domestic-use seasons. Water consumption in cubic meters, gas consumption in cubic meters, and electricity consumption in kilowatt-hours were obtained from the Tehran Water and Wastewater Company, the Tehran Gas Company, and the Tehran Electricity Distribution Company, matched to households through meter codes and georeferenced building identifiers. A structured survey campaign at 41 randomly selected sampling points, covering villas, apartment buildings, and deteriorated structures, gathered information on household size, building age and quality, orientation, number of floors, dwelling area, land-use type, and transportation accessibility. Quality-control steps included cross-checking utility logs against district averages, revisiting 10 percent of surveyed households for verification, validating building attributes against cadastral maps, removing statistical outliers, and performing GIS topology checks. All data were integrated into a unified GIS database, and spatial patterns were mapped in ArcGIS.
With the dataset in hand, the researchers turned to four machine-learning algorithms: Random Forest, Multi-Layer Perceptron, Gaussian Process with a Radial Basis Function kernel (GP-RBF), and Gaussian Process with a Pearson Universal Kernel (GP-PUK). The models were implemented in the WEKA software environment, with hyperparameters tuned exclusively on the training subset using repeated 10-fold cross-validation to avoid information leakage from the test data. Seventy percent of the data was allocated for model training and the remaining 30 percent for testing. The input variables were seven building-level predictors: building area, building orientation, building quality, number of family members, number of floors, transportation access, and land use. The outputs were monthly water, gas, and electricity consumption values recorded over twelve months. Model performance was evaluated with three standard metrics: the correlation coefficient (CC), root mean square error (RMSE), and mean absolute error (MAE), with the best model for each resource type selected primarily on testing-phase correlation.
The results revealed a strikingly uneven picture across the three resource types, and the authors themselves urge caution in interpreting several of the headline numbers. For water consumption, the GP-RBF model achieved a near-perfect fit during training, with a correlation coefficient of 0.99, but its performance collapsed in testing, where the correlation dropped to 0.42 with an RMSE of 0.24 and an MAE of 0.19. The study attributes this decline to partial overfitting, meaning the model captured patterns in the training data that did not generalize to unseen observations. The authors explicitly state that no model achieved high generalization for water consumption and that claims of strong robustness are not warranted. For electricity, the GP-PUK model delivered the most stable testing performance, with a correlation coefficient of 0.71, RMSE of 0.18, and MAE of 0.13, after both Gaussian Process variants posted near-perfect training fits. For gas, GP-RBF achieved the highest testing correlation at 0.49, though the Random Forest model produced a lower mean absolute error.
The electricity results deserve particular attention because they illustrate both the promise and the limits of the approach. During training, GP-RBF and GP-PUK both achieved correlation coefficients of 0.99, while the Multi-Layer Perceptron reached 0.92 and Random Forest 0.67. In testing, however, the MLP and GP-RBF models suffered sharp declines, falling to correlation coefficients of 0.67 and 0.61 respectively, which the authors interpret as evidence of overfitting, with the models memorizing training noise rather than learning generalizable trends. The GP-PUK model, by contrast, retained the highest testing correlation and was identified as the most robust option for electricity prediction in the district. Even so, the study notes that several testing samples showed pronounced deviations, particularly around peak consumption cases, and that the model’s generalization capability should be regarded as moderate rather than strong. The electricity figures were derived from normalized data and should be interpreted accordingly.
Perhaps the most consequential findings came from the sensitivity analysis, in which each input variable was omitted individually and the resulting changes in model performance were examined. For water consumption, building quality emerged as the most influential predictor: removing it caused the correlation coefficient to fall from 0.42 to 0.18, while removing building area reduced the correlation to 0.21. For electricity, building quality was again dominant, with its omission driving the correlation coefficient down from 0.61 to 0.06. In contrast, removing land use, transportation access, or number of floors sometimes produced higher correlation coefficients than the baseline, suggesting those variables may contribute noise rather than predictive strength. The pattern was most dramatic for gas consumption: when land use was removed from the GP-PUK model, the correlation coefficient jumped from 0.47 to 0.99, RMSE fell from 0.39 to 0.11, and MAE declined to 0.07, indicating that land-use information actively degraded the gas model’s stability in this dense, aging neighborhood.
These sensitivity results carry implications for how urban regeneration policy might be targeted. Across all three energy types, structural building attributes, especially quality and area, proved more influential than spatial-functional variables such as land use or transportation access. The authors suggest that the strong role of building quality likely reflects differences in insulation, plumbing integrity, appliance efficiency, and heating systems, with poor-quality buildings experiencing higher leakage, inefficient fixtures, and greater heating losses. Larger units, meanwhile, contain more fixtures, appliances, and heated volume, raising overall demand. The study is careful to note that the sensitivity results do not indicate whether the number of floors increases or decreases consumption, and that any explanation involving shared plumbing or vertical efficiency must be treated as a possible mechanism rather than a confirmed causal relationship. The limited influence of land use and transportation suggests that in older urban districts, household-level structural factors may outweigh neighborhood-level spatial characteristics.
Based on these patterns, the authors propose that renovation programs in deteriorated districts should prioritize building-quality improvements, including plumbing upgrades, insulation, and heating systems, which directly affect water and gas consumption. They also recommend targeting structural retrofits that enhance building-area efficiency through fixture replacement, appliance upgrades, and improved thermal performance, and they caution that zoning-based energy policies should be applied carefully in dense, aging neighborhoods where land use did not improve model performance. Because water, electricity, and gas consumption responded to different sets of predictors, the study argues that regeneration policies must be energy-type-specific rather than uniform. The spatial mapping added further texture: water consumption peaked in the northwestern part of the district, electricity demand was greatest in the eastern and central zones, and gas use was highest in the northwest, central, and western areas, reflecting differences in building typologies, household characteristics, and micro-climatic conditions.
The study’s limitations are acknowledged plainly by its authors. The dataset comprises only 41 observations, which restricts the statistical power of the models and limits the generalizability of the findings to broader urban contexts. Several predictors may also be correlated with one another, potentially influencing the sensitivity-analysis results and obscuring the true independent contribution of each variable. The moderate testing performance for the water and gas models, together with evidence of overfitting, means the results should be read as exploratory rather than definitive. The authors call for future research to expand the dataset to multiple districts and time periods, apply directional effect analysis using tools such as partial dependence plots and SHAP values to determine whether variables increase or decrease consumption, explore hybrid modeling approaches combining Gaussian Process models with deep learning, and investigate behavioral factors such as occupancy patterns, appliance usage, and heating habits.
For a field increasingly interested in the intersection of data science and urban planning, the study offers a measured contribution: it demonstrates that Gaussian Process regression can capture nonlinear relationships between building characteristics and household resource use, while also showing how easily small-sample models can overfit and how variable selection can reshape conclusions. In a district where hot summers and cold winters drive substantial seasonal demand for cooling and heating, and where the aging building stock presents both a challenge and an opportunity for regeneration, the finding that building quality dominates consumption patterns is a practical one. Whether the same hierarchy of predictors holds in larger, more diverse datasets remains an open question, and the authors are careful not to claim more than their 41 sampling points can support. What the work does establish is a documented, reproducible framework, from utility-record matching to cross-validated model tuning, that future studies of energy-efficient urban regeneration can build upon and test at scale.
Subject of Research: Machine-learning modeling of household water, electricity, and gas consumption in a deteriorated district of Tehran
Article Title: Machine learning-based analysis of urban regeneration and household energy consumption for sustainable energy optimization in deteriorated urban areas
Article References: Shamaei, A., & Jafarpour Ghalehteimouri, K. (2026). Machine learning-based analysis of urban regeneration and household energy consumption for sustainable energy optimization in deteriorated urban areas. City and Built Environment, 4(1), Article 18. https://doi.org/10.1007/s44213-026-00085-8
Image Credits: AI Generated
DOI: 10.1007/s44213-026-00085-8
Keywords: machine learning, urban regeneration, household energy consumption, Gaussian Process regression, Tehran, building quality, water consumption, electricity demand, gas consumption, sensitivity analysis, deteriorated urban fabric, energy efficiency
Cite Scienmag News
Teresa Odom. (October 28, 2026). Machine learning probes household energy use in Tehran’s aging districts. Scienmag. https://scienmag.com/machine-learning-probes-household-energy-use-in-tehrans-aging-districts/
Teresa Odom. "Machine learning probes household energy use in Tehran’s aging districts." Scienmag, 28 October 2026, https://scienmag.com/machine-learning-probes-household-energy-use-in-tehrans-aging-districts/. Accessed 28 October 2026.
Teresa Odom. "Machine learning probes household energy use in Tehran’s aging districts." Scienmag. October 28, 2026. https://scienmag.com/machine-learning-probes-household-energy-use-in-tehrans-aging-districts/