

Gluten is the invisible architecture of the bakery world. The stretchy protein network that traps gas bubbles in a rising loaf, gives pizza dough its chew, and lets a croissant shatter into delicate layers is what separates bread flour from cookie flour at the most fundamental level. For millers, bakers, and plant breeders, knowing exactly how much gluten a flour contains and how strong that gluten network is has always required a slow, wet, destructive laboratory ritual. Now, a research team in China has shown that a pocket-sized near-infrared spectrometer, paired with a clever new mathematical trick, can read those same quality traits straight from whole wheat flour in seconds, with accuracy that rivals the reference methods themselves.
The study, published in Food Chemistry: X, tackled a problem that has long frustrated the grain industry. The official national standard procedures for measuring gluten properties, defined in Chinese standards GB/T 5506.2-2024 and GB/T 5506.4-2008, involve mixing flour with salt solution, kneading a dough, washing away the starch through a fine sieve, centrifuging the sticky residue, and drying it to a crisp. The process is tedious, demands skilled operators, destroys the sample, and consumes substantial reagents. That may be tolerable for a quality control bench, but it is hopeless for the modern demands of real-time process adjustment in mills, online grading of incoming grain, and the high-throughput genotype screening that accelerates breeding programs. Breeders evaluating hundreds of experimental wheat lines simply cannot wash dough fast enough.
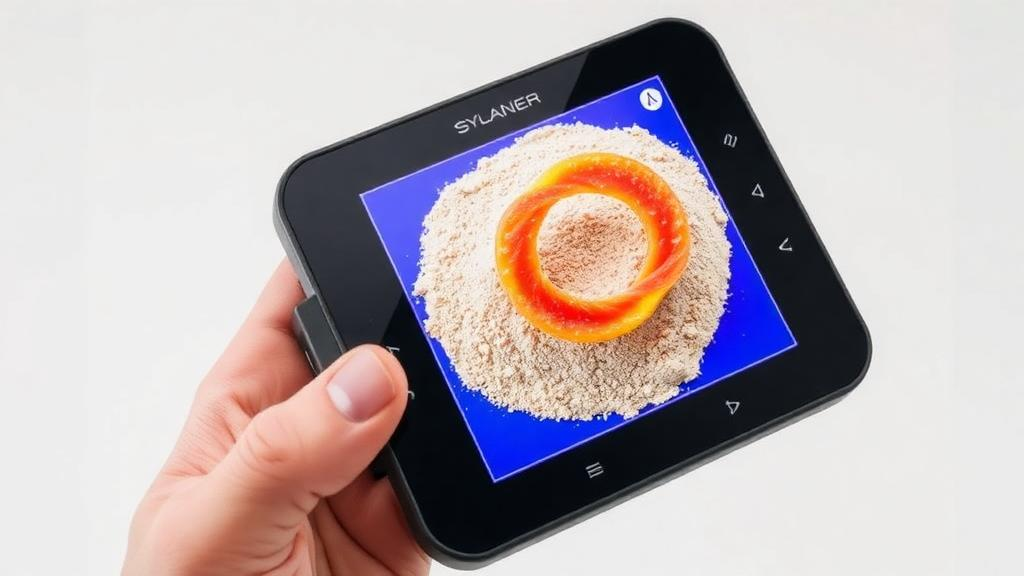
Near-infrared spectroscopy has long promised a way out. Because the overtones and combination vibrations of hydrogen-bearing bonds in the 930 to 1630 nanometer range carry fingerprints of the organic molecules in a sample, a handheld DLP NIRscan Nano spectrometer can press against a flour surface and capture 389 spectral dimensions in moments. The research team, led by Rui Zhang and colleagues, applied the instrument to whole wheat flour milled from 100 verified wheat varieties grown in Beijing’s Shunyi district, with each variety’s identity confirmed by SSR molecular markers at the Beijing Wheat Seed Testing Center. From each sample they collected ten spectral readings and averaged them, calibrating against a white reference roughly every twenty scans to keep the instrument honest.
The targets of prediction were five gluten-related indicators. Wet gluten content, its moisture-corrected variant on a 14 percent moisture basis, and dry gluten content describe the quantity of gluten proteins, chiefly glutenin and gliadin. Wet gluten remaining on the sieve after centrifugation and the gluten index, the proportion of wet gluten that stays on the sieve, describe the strength and elasticity of the gluten network. In the sample set, wet gluten content hovered around 35 percent with a narrow range, while the gluten index spanned nearly the full 0 to 1 scale, from 0.01 to 1.00, offering the model a wide and challenging spread of quality to learn from. Correlation analysis revealed that the two strength indicators moved together almost perfectly, with a correlation coefficient of 0.955, while the content indicators formed their own tightly linked cluster.
The first innovation came before any modeling at all: how to split 100 samples into training and test sets. The classic Kennard-Stone algorithm and its extension, SPXY, both rely on Euclidean distances that implicitly assume the response variables are independent. But gluten indicators are anything but independent, as the strong correlations show. The team therefore proposed a covariance-guided stratified sampling strategy, or CGSS, which computes the covariance matrix of the response matrix, extracts its dominant eigenvector, and projects each sample’s centered response vector onto that principal axis of joint variation. Samples are then partitioned so that both training and test sets cover this composite quality axis evenly. On every evaluation metric, from normalized mean difference to range coverage, CGSS produced training and test sets that matched each other more closely than either classical method, achieving full spectral coverage of the test set by the training set and visibly more uniform scatter in the quality indicator space.
The second and more surprising innovation addressed the target variables themselves. Rather than feeding raw gluten measurements into a regression model, the researchers built what they call a bilinear surface function model. Each target value is normalized, then multiplied by a weight function controlled by a single hyperparameter alpha, which was tuned to 1.8425 through partial least squares regression with ten-fold cross-validation. The transformed variable encodes prior knowledge about how the gluten indicators relate to one another, effectively letting the model exploit the correlation structure among the five responses instead of treating each as an isolated number. A regularized inverse regression then reconstructs the actual predicted values. The effect was dramatic. With raw spectra and ordinary partial least squares regression, the test coefficient of determination for the gluten index was a dismal 0.17. After the surface transformation, it leapt to 0.86, and wet gluten remaining on the sieve climbed from 0.05 to 0.73.
Spectral preprocessing told an instructive cautionary tale. Multiplicative scatter correction, standard normal variate, first derivative, and detrending were each tested, and most either failed to help or actively hurt. First-derivative processing, in particular, degraded the surface-model results, dropping most test R-squared values below 0.5, apparently because differentiation amplifies noise and discards key spectral information. Detrending, by contrast, removed baseline drift and pushed the dry gluten prediction to 0.89. The lesson, consistent with a growing body of critique in the chemometrics literature, is that aggressive preprocessing is not automatically beneficial; sometimes the raw spectrum already contains what the model needs, and correction steps can distort or amplify noise at the expense of the analyte signal.
The full pipeline then coupled three wavelength selection methods, the successive projections algorithm, competitive adaptive reweighted sampling, and principal component analysis, with five machine learning regressors: quantile gradient boosting, elastic net, ridge, LASSO, and partial least squares. LASSO emerged as the clear winner in every configuration, a result the authors attribute to its sparsity advantage in high-dimensional spectral data, where it shrinks irrelevant coefficients to exactly zero and avoids overfitting the limited sample set. The best overall combination was CARS wavelength selection plus the bilinear surface model plus LASSO. On the independent test set, the coefficients of determination reached 0.98 for wet gluten remaining on the sieve, 0.93 for the gluten index, 0.89 for dry gluten content, 0.84 for wet gluten content, and 0.83 for the moisture-corrected variant. The corresponding RPD values, a robustness metric where anything above 2.0 is considered suitable for analytical purposes, were 6.73, 3.77, 3.08, 2.47, and 2.40, placing every indicator comfortably in the high-reliability zone.
What makes this work resonate beyond the laboratory is the combination of hardware and mathematics. The spectrometer is a handheld consumer-grade device, not a benchtop instrument, which means the entire analytical chain could in principle run at a grain elevator, in a breeding nursery, or on a mill floor. And because a single unified model predicts all five gluten indicators simultaneously, it avoids the fragmented approach of maintaining separate calibrations for each trait, which earlier studies required. The authors are careful to note that further validation is needed to assess performance in practical, real-world deployment, and the sample set of 100 varieties from one district and one season is modest by industrial standards. Still, the framework offers something the wet-chemistry standards never could: a nondestructive, reagent-free, seconds-per-sample measurement of both how much gluten a whole wheat flour contains and how strong that gluten will be, which is precisely the information breeders and millers need to sort the bread wheats from the cookie wheats at scale.
Subject of Research: Rapid nondestructive determination of gluten content and strength in whole wheat flour using near-infrared spectroscopy with a bilinear surface model and machine learning
Article Title: Bilinear surface model-enhanced determination of gluten quality in whole wheat flour by NIR spectroscopy
Article References: Zhang, R., Qu, P., Sun, H., Feng, G., Liu, L., Pan, D., & Luo, B. (2026). Bilinear surface model-enhanced determination of gluten quality in whole wheat flour by NIR spectroscopy. Food Chemistry: X, Article 104541. https://doi.org/10.1016/j.fochx.2026.104541
Image Credits: AI Generated
DOI: 10.1016/j.fochx.2026.104541
Keywords: near-infrared spectroscopy, whole wheat flour, gluten quality, gluten index, wet gluten content, LASSO regression, chemometrics, machine learning, sample partitioning, bilinear surface model, wheat breeding, food quality detection
Cite Scienmag News
Alan Morgan. (October 5, 2026). Handheld NIR Scanner and Bilinear Surface Model Crack Rapid Gluten Quality Testing in Whole Wheat Flour. Scienmag. https://scienmag.com/handheld-nir-scanner-and-bilinear-surface-model-crack-rapid-gluten-quality-testing-in-whole-wheat-flour/
Alan Morgan. "Handheld NIR Scanner and Bilinear Surface Model Crack Rapid Gluten Quality Testing in Whole Wheat Flour." Scienmag, 5 October 2026, https://scienmag.com/handheld-nir-scanner-and-bilinear-surface-model-crack-rapid-gluten-quality-testing-in-whole-wheat-flour/. Accessed 5 October 2026.
Alan Morgan. "Handheld NIR Scanner and Bilinear Surface Model Crack Rapid Gluten Quality Testing in Whole Wheat Flour." Scienmag. October 5, 2026. https://scienmag.com/handheld-nir-scanner-and-bilinear-surface-model-crack-rapid-gluten-quality-testing-in-whole-wheat-flour/


