

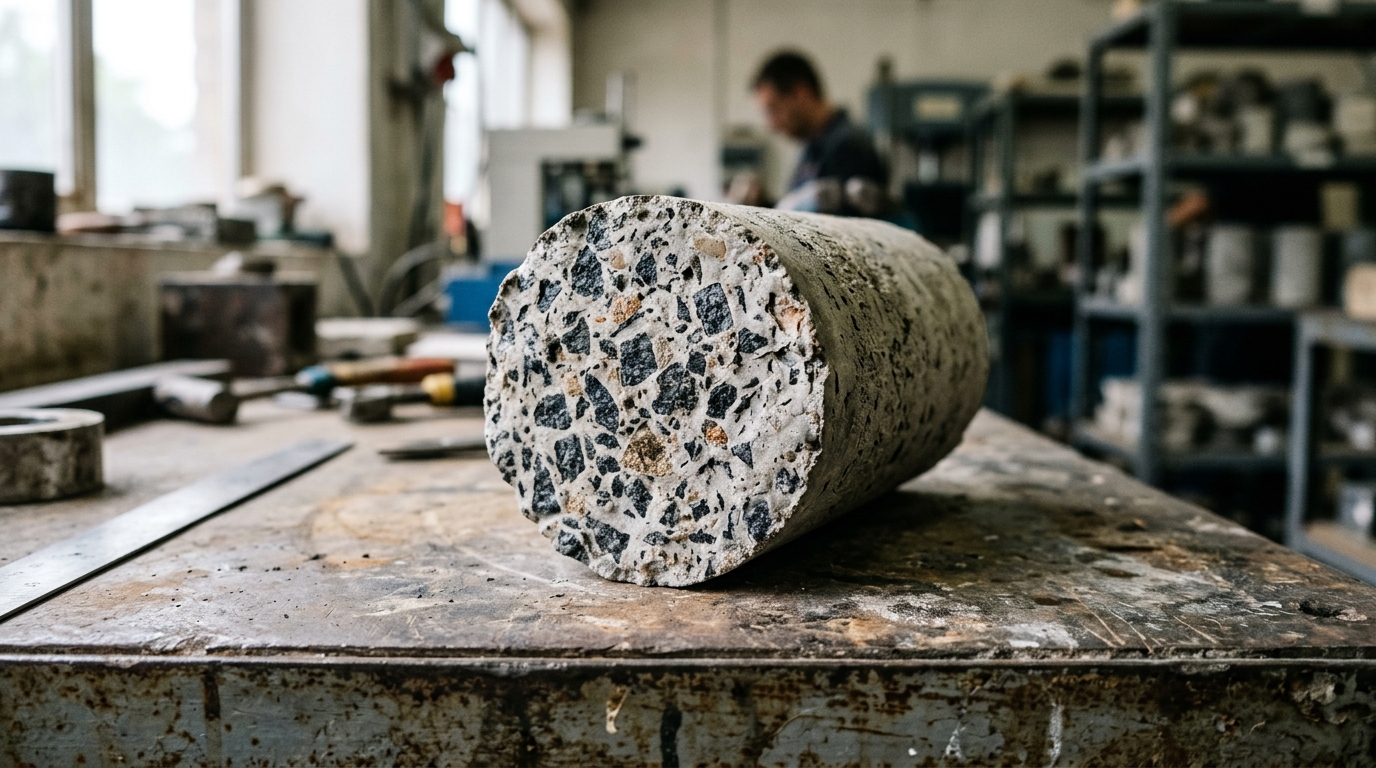
Concrete is the most widely used construction material in the world, and its compressive strength is the property on which structural safety, mixture design and quality control all depend. Measuring it traditionally means casting specimens and waiting through designated curing ages in a laboratory, a process that is expensive, slow and dependent on prolonged preparation. A study published in Discover Civil Engineering now reports a hybrid machine learning framework that predicts this strength directly from mixture data, achieving a coefficient of determination of 0.936, a mean absolute error of 2.695 MPa and a root mean squared error of 4.071 MPa on a benchmark dataset of 1,030 concrete mixtures.
The work, led by Md. Siam Ansary and published open access on 2 November 2026, combines several techniques that have usually appeared separately in earlier studies. At its core is a stacking ensemble: three gradient boosting algorithms, namely XGBoost, LightGBM and CatBoost, each serve as a base learner, and their predictions are merged by an ElasticNet regression meta-learner. Hyperparameters for every model were tuned automatically with the Optuna framework, which ran 40 independent trials per base learner, each evaluated with 5-fold cross-validation on the training set, maximising the mean validation R².
What distinguishes the framework from many prior models is the way engineering knowledge is built into the data before any algorithm sees it. Six physically meaningful features were derived from the eight raw input variables, which record cement, blast furnace slag, fly ash, water, superplasticizer, coarse aggregate and fine aggregate contents in kilograms per cubic metre, plus curing age in days. The derived variables include binder content, the sum of cement, slag and fly ash; the water-to-binder ratio; the water-to-cement ratio; the superplasticizer-to-binder ratio; the coarse-to-fine aggregate ratio; and a logarithmically transformed curing age, reflecting the logarithmic nature of strength gain over time. This expands the feature space from 8 to 14 features before any further processing.
On top of these domain-derived features, the study generates second-order polynomial interaction features, capturing pairwise products of variables while deliberately excluding pure quadratic terms to avoid inflating model variance. The authors justify this step physically: the water-to-cement ratio controls the degree of cement hydration and capillary porosity, with higher ratios increasing porosity and lowering strength; fly ash and blast furnace slag participate in secondary pozzolanic reactions that convert calcium hydroxide into additional calcium silicate hydrate gel; and aggregate packing density and the aggregate-to-paste ratio influence the quality of the interfacial transition zone. Such joint effects, for example the combined influence of water and binder composition or of curing age and fly ash content, are not captured by individual feature effects alone. The interaction terms are described as particularly beneficial for the linear ElasticNet meta-learner, which cannot discover interactions on its own.
Methodological rigour receives explicit attention. The dataset was split 80/20 into training and test sets with a fixed random seed of 42, and z-score normalisation was applied. Critically, all scaling and feature engineering transformations were fitted exclusively on the training fold and then applied to the test fold, and during cross-validation these operations were repeated independently within each fold. The meta-learner was trained exclusively on out-of-fold predictions generated through 5-fold cross-validation on the training set, with base learners retrained on the full training set afterwards to produce test-set predictions. The authors argue that this leakage-free pipeline, together with out-of-fold meta-learning, addresses a persistent weakness in earlier stacking studies.
The performance figures place the model among the strongest reported on this benchmark. An R² of 0.936 means the model explains approximately 93.6 percent of the variance in compressive strength, while the mean absolute error of 2.695 MPa represents less than 7.5 percent of the mean target value of 35.82 MPa. In a direct comparison on the same test set and feature set with default hyperparameters, the stacking ensemble outperformed all individual algorithms tested, including random forests, extra trees, support vector regression and multilayer perceptron neural networks. The gradient boosting models achieved the best individual results, but stacking delivered a further gain of roughly 0.6 MPa in root mean squared error and about 2 percentage points in R² over the best single model, CatBoost with default settings, which the authors interpret as evidence of a genuine architectural contribution from the ensemble itself rather than merely a fortunate choice of base learner.
An ablation study dissects which components matter most. A single XGBoost model on the eight raw features established a baseline with a mean absolute error of 2.996, a root mean squared error of 4.606 and an R² of 0.918. Adding the domain-derived features modestly improved the error metrics while R² remained unchanged at 0.918. Interestingly, polynomial interaction features applied to a single XGBoost model degraded performance, raising the mean absolute error to 3.439 and the root mean squared error to 5.441 with R² falling to 0.885, apparently because the added dimensionality brought no proportional information gain for a tree-based model. Optuna tuning of a single XGBoost also failed to beat the baseline. Only the full stacking configuration, combining feature engineering, interaction features, optimisation and the ensemble, reached the best figures on every metric, leading the authors to conclude that the stacking architecture is the most impactful component of the framework.
Interpretability was addressed through SHAP, or SHapley Additive exPlanations, which decompose each prediction into additive feature contributions. Cement content emerged as the dominant predictor with a mean absolute SHAP value of 6.92 MPa, consistent with its central role in strength development through hydration. The log-transformed curing age ranked second at 4.85 MPa, capturing time-dependent strength gain. Notably, the water-to-binder ratio, a domain-derived variable absent from the original dataset, ranked third at 2.87 MPa, which the authors present as validation that their feature engineering contributes meaningful predictive signal beyond the raw measurements. The parity plot for the test set showed points clustering tightly around the diagonal across the full strength range, and the residual plot displayed no systematic pattern, indicating unbiased predictions with homogeneous error variance.
The authors are candid about the scope of the contribution. They position the model as a decision-support tool for data-driven mixture design evaluation rather than an optimisation algorithm, allowing engineers to screen mixture configurations rapidly before laboratory validation. They also note that polynomial interaction features, while harmful to a single tree-based model, provide useful interaction signals to the linear meta-learner within the full stack. Training all Optuna trials took approximately 45 minutes on standard hardware, an Intel Core i7 with 16 GB of RAM, and inference is fast, at under one millisecond per sample. The software stack comprised Python 3.10, scikit-learn 1.4.0, XGBoost 2.0.3, LightGBM 4.3.0, CatBoost 1.2.2, Optuna 3.5.0 and SHAP 0.44.0.
Limitations are acknowledged in detail. The dataset represents laboratory-scale experiments, whereas real-world production involves unmodelled variables such as environmental conditions, mixing procedures and material variability. The 1,030-sample collection, drawn from the UCI Machine Learning Repository, is moderate relative to industrial production volumes. The study models compressive strength only, leaving tensile strength, durability and permeability unaddressed, and the training time may become prohibitive for much larger datasets. The authors also stress that deploying the model in structural design requires domain expert review and experimental validation of predicted mixture designs. Future directions they outline include incorporating larger industrial datasets with environmental and process variables, multi-task learning for simultaneous prediction of multiple concrete properties, physics-informed neural networks embedding hydration model constraints, uncertainty quantification through conformal prediction or Bayesian approaches, and a lightweight deployment interface for practical mixture design support.
Subject of Research: Machine learning prediction of concrete compressive strength using a stacking ensemble with domain-informed feature engineering
Article Title: A hybrid stacking ensemble framework with domain-informed feature engineering for accurate prediction of concrete compressive strength
Article References: Ansary, M. S. (2026). A hybrid stacking ensemble framework with domain-informed feature engineering for accurate prediction of concrete compressive strength. Discover Civil Engineering, 3(1), Article 272. https://doi.org/10.1007/s44290-026-00667-9
Image Credits: AI Generated
DOI: 10.1007/s44290-026-00667-9
Keywords: concrete compressive strength, machine learning, stacking ensemble, XGBoost, LightGBM, CatBoost, feature engineering, SHAP interpretability, Optuna, hyperparameter optimization, civil engineering, UCI dataset
Cite Scienmag News
Teresa Odom. (November 8, 2026). Stacked machine learning model predicts concrete strength with high accuracy. Scienmag. https://scienmag.com/stacked-machine-learning-model-predicts-concrete-strength-with-high-accuracy/
Teresa Odom. "Stacked machine learning model predicts concrete strength with high accuracy." Scienmag, 8 November 2026, https://scienmag.com/stacked-machine-learning-model-predicts-concrete-strength-with-high-accuracy/. Accessed 11 November 2026.
Teresa Odom. "Stacked machine learning model predicts concrete strength with high accuracy." Scienmag. November 8, 2026. https://scienmag.com/stacked-machine-learning-model-predicts-concrete-strength-with-high-accuracy/




