

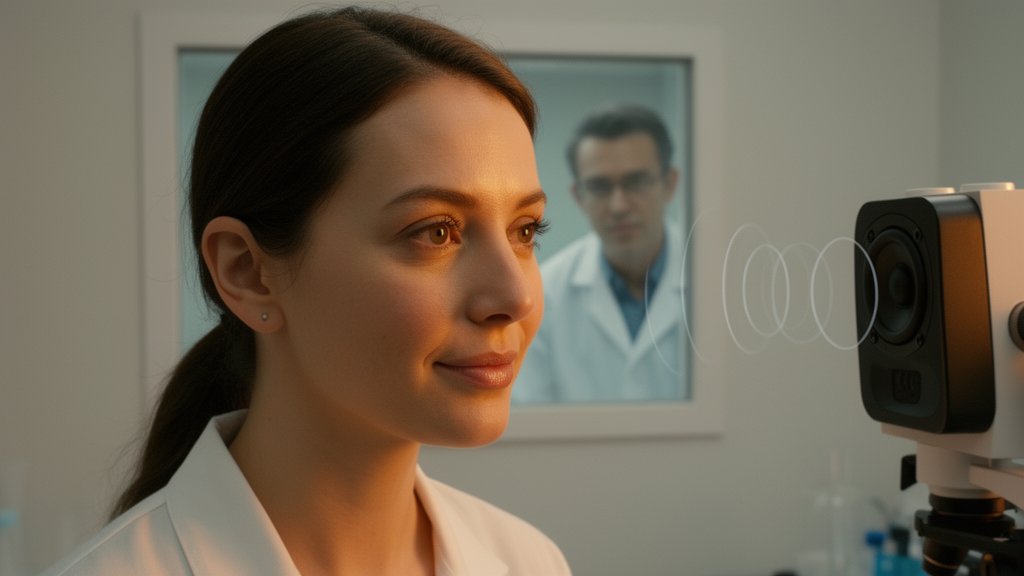
Every social interaction depends on a remarkable feat of neural computation: within a fraction of a second, the brain must extract emotional meaning from two very different kinds of signals. A furrowed brow and a trembling voice carry the same message of distress, yet one arrives as patterns of light on the retina and the other as fluctuations in air pressure. A new study published in JNeurosci, the journal of the Society for Neuroscience, reveals how the brain accomplishes this translation, showing that the neural systems dedicated to faces and voices do not operate in isolation but share a common emotional code that allows information from sight and sound to be merged into a single, rapidly formed impression of how another person feels.
The research was led by Olivier Collignon of the Catholic University of Louvain and Stefania Mattioni, currently at Ghent University, together with colleagues who set out to map how the human brain responds to emotional expressions delivered through different sensory channels. Their central question was deceptively simple: when we see an angry face or hear an angry voice, does the brain treat these as entirely separate problems, or does it represent the underlying emotion in a way that transcends the sense through which it arrives? The answer, according to their findings, leans strongly toward the second possibility, with important consequences for understanding how humans achieve such fast and fluent social perception.
To probe this question, the team measured brain activity while participants perceived emotional faces and emotional voices, first presenting each type of stimulus separately and then examining what happened when the two modalities appeared together. The experimental logic relied on the fact that certain cortical regions respond preferentially to faces, while others respond preferentially to voices. If emotional information were confined strictly within these modality-specific systems, then face-selective areas should encode only what is seen and voice-selective areas only what is heard. The data told a different story.
When participants perceived faces or voices on their own, the emotions being expressed triggered widespread activity across brain areas that respond to faces and voices. Crucially, this activity was not neatly partitioned along sensory lines. As Mattioni explained, several face-selective regions also carried information about emotions heard in voices, while voice-selective regions carried information about emotions seen in faces. In other words, the brain’s visual and auditory specialist areas were not sealed compartments but porous networks, each holding traces of emotional content that had entered through the other sense.
Even more striking was the discovery that in some regions the brain represented the same emotion similarly whether it was seen or heard. This finding points to a shared representational format, a kind of neural common currency for emotion, in which the identity of an emotional state is encoded independently of the sensory channel that delivered it. Such a format would be enormously useful: it would allow the brain to compare, match, and integrate what the eyes report with what the ears report, without needing to translate between incompatible codes. It also offers a mechanistic explanation for the everyday experience of instantly grasping someone’s mood from a glance and a tone of voice simultaneously.
The study went a step further by examining what happens when faces and voices are perceived together, a condition that mirrors real social encounters far more closely than isolated stimuli. The researchers found that this audiovisual combination reshaped how the brain processed and evaluated emotions compared with faces or voices alone. Integration, in this view, is not merely the addition of two separate signals. Instead, the joint presence of congruent visual and auditory emotional information changes the neural response itself, altering the way emotional expressions are computed across the network of face- and voice-sensitive regions.
From a technical perspective, these results speak to a long-running debate in cognitive neuroscience about whether social signals are processed by dedicated, modality-specific modules or by supramodal systems that abstract away from the particular sense of arrival. The new evidence supports a hybrid architecture. Face-selective and voice-selective regions retain their sensory preferences, yet they also participate in a distributed emotional code that crosses sensory boundaries. This arrangement would explain both the speed of emotion recognition and its robustness: if one channel is degraded, for example by noise or poor lighting, the shared representation can still be accessed through the other channel.
The findings also carry implications for understanding social perception as an actively constructive process rather than a passive reading of expressions. Because the combined presentation of faces and voices changed the brain’s response, emotional understanding appears to emerge from dynamic interactions between sensory systems rather than from a pipeline in which each sense delivers its verdict independently. This perspective aligns with the everyday observation that a facial expression can sound different depending on the voice that accompanies it, and that a tone of voice can alter how we interpret the face above it.
Beyond its theoretical significance, the work opens a path toward clinical questions. The authors note that their findings could inform future research on whether these cross-sensory emotional mechanisms are impaired in individuals who struggle to integrate social cues. Conditions in which social communication is difficult often involve problems in combining information from multiple sources, and the neural framework described in this study provides a concrete target for such investigations. If the shared emotional representations identified here can be measured reliably, they may eventually serve as markers for atypical social processing and as endpoints for interventions aimed at improving multisensory integration.
The study, titled Representation of Emotional Expressions Across the Face and Voice Brain Networks, was published in JNeurosci on 19 October 2026, with the authors declaring no competing financial interests. Its central message is one of neural teamwork: the brain systems that process faces and voices interact, and in some areas represent emotions in a similar way, allowing humans to build a fast understanding of how another person is feeling by combining what they see in the face with what they hear in the voice. In a world where social connection depends on reading countless fleeting signals, the brain appears to have evolved a solution in which the senses speak a common emotional language.
Subject of Research: Neural representation and cross-sensory integration of emotional expressions in face- and voice-selective brain networks
Article Title: How do people quickly recognize what others may be feeling?
Article References: How do people quickly recognize what others may be feeling?. Original publication (Bibliographic details unavailable.)
Image Credits: AI Generated
DOI: Not provided
Keywords: emotion recognition, face perception, voice perception, multisensory integration, JNeurosci, social neuroscience, face-selective regions, voice-selective regions, emotional expressions, brain imaging, Society for Neuroscience, cross-modal representation
Cite Scienmag News
Cassandra Pierce. (October 19, 2026). How the Brain Reads Emotions From Faces and Voices at the Same Time. Scienmag. https://scienmag.com/how-the-brain-reads-emotions-from-faces-and-voices-at-the-same-time/
Cassandra Pierce. "How the Brain Reads Emotions From Faces and Voices at the Same Time." Scienmag, 19 October 2026, https://scienmag.com/how-the-brain-reads-emotions-from-faces-and-voices-at-the-same-time/. Accessed 19 October 2026.
Cassandra Pierce. "How the Brain Reads Emotions From Faces and Voices at the Same Time." Scienmag. October 19, 2026. https://scienmag.com/how-the-brain-reads-emotions-from-faces-and-voices-at-the-same-time/


