

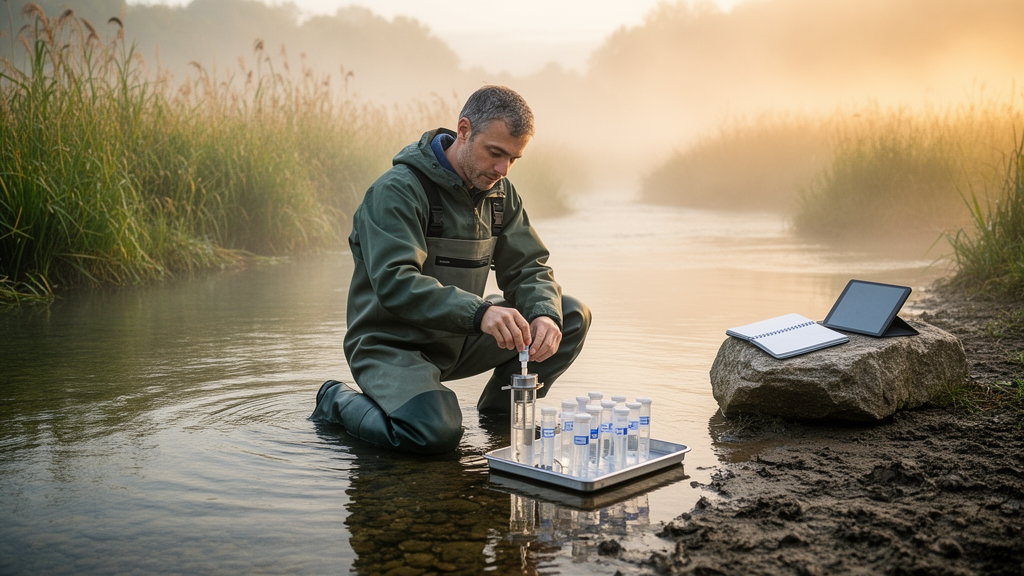
Environmental DNA has been hailed as the most transformative biodiversity monitoring tool in decades, and across Europe it is already delivering on that promise. By sequencing the genetic material that fish, invertebrates, protists and other organisms continuously shed into water through skin cells, scales, mucus and faeces, researchers can detect elusive, rare and invasive species with a sensitivity that traditional surveys simply cannot match. A single water sample can reveal an entire ecological community, without nets, traps or disturbance to fragile habitats. But a major new assessment of the European aquatic eDNA landscape warns that this revolution is quietly being undermined by a problem most people never see: the data behind the headlines are far less complete, consistent and reusable than the science community believes.
The study, published in the journal Metabarcoding and Metagenomics as part of the Horizon Europe project eDNAqua-Plan, took an unusually comprehensive look at how eDNA data are generated, archived and shared across the continent. Rather than relying on a single method, the team combined four complementary approaches: a qualitative evaluation of the major databases that store eDNA records, a quantitative audit of metadata completeness, a questionnaire survey of 69 researchers from 29 countries, and a large-scale analysis of more than 1,600 scientific publications using a fine-tuned large language model. The verdict is stark. While some repositories demonstrate strong curation and accessibility, others lack essential metadata descriptors, and the gaps are heavily concentrated in exactly the areas that determine whether data can ever be reused.
The technical core of the problem lies in metadata, the structured information that describes how each sample was collected, processed and sequenced. Without knowing the filter pore size used to capture DNA particles, the volume of water extracted, the primers deployed during PCR amplification, or the bioinformatic pipeline applied to the raw reads, a downstream user cannot meaningfully compare one dataset with another. The international standards designed to solve this exist. The Genomic Standards Consortium’s MIxS framework defines mandatory and recommended metadata terms for sequence submissions, including a Water extension with fields such as size_frac_low and samp_vol_we_dna_ext. The Darwin Core standard underpins biodiversity platforms like GBIF and OBIS. Yet the audit of 5,280 European aquatic eDNA sample accessions in the European Nucleotide Archive revealed that these standards are being applied only patchily.
The numbers are remarkable. Although every retrieved sample carried the mandatory environmental context fields, Environment Ontology terms appeared in only about 18 percent of entries. The sample collection method was provided in fewer than 20 percent of records, and the size fraction used for pre-filtration in just 13.5 percent. The volume or mass of sample used for DNA extraction was reported in a mere 1.5 percent of cases, and the nucleic acid extraction method in 2 percent. PCR primers, a critical determinant of taxonomic coverage and amplification bias, were given for 23 percent of records, while the target gene fragment appeared in only 2 percent. Even the MIxS term nucl_acid_ext, designed specifically to hold extraction protocol information, did not appear in a single record. In practice, much of the metadata that does exist was submitted as inconsistent free text rather than standardised values, forcing anyone hoping to harmonise the data into laborious manual curation.
The questionnaire survey exposed a second, more troubling layer to the problem: a significant gap between what researchers believe they are doing and what the repositories actually record. Respondents reported higher compliance with metadata submission practices than the automated audit revealed. Sampling methods were reported by 59 percent of survey participants and DNA extraction protocols by 51 percent, yet the actual BioSample records showed far lower volumes of reported metadata. The authors attribute this mismatch to a combination of survey biases, including self-selection of more engaged respondents and social desirability bias, alongside structural factors such as misperceptions of the full scope of metadata requirements, lack of training, the complexity of submission systems, time constraints and limited incentives or enforcement.
The large language model analysis added a third dimension by revealing how these weaknesses recur across the literature itself. The team assembled 117 manually curated publications as a training set, then used a fine-tuned Llama 2 model to automatically extract methodological information from an expanded corpus of 1,607 eDNA papers, achieving validation accuracy of 97 to 99 percent. The synthesis showed a strong concentration of studies around a limited set of genetic markers, with the mitochondrial COI marker most frequently reported at 19 percent, followed by 16S rRNA at 17 percent and ITS at 14.5 percent. GenBank dominated as the reference database for taxonomic assignment, cited in 19.7 percent of papers where the model could infer one, with SILVA at 18.3 percent and BOLD at 9.9 percent. But the most striking finding concerned protocol transparency: of 1,440 publications for which methodological information could be inferred, only six, or 0.4 percent, cited experimental protocols deposited in protocols.io, and none of those protocol DOIs appeared in the formal reference sections of the papers.
Geographic disparities compound the technical gaps. Analysis of European aquatic eDNA sequence records in the International Nucleotide Sequence Database Collaboration, which comprises ENA, NCBI and the DNA Data Bank of Japan, revealed that records are heavily concentrated in Northern and Western European countries, while Eastern and Southeastern Europe contribute substantially fewer. The imbalance reflects not just differences in sequencing volume but disparities in project-level participation, suggesting that in some regions DNA research activity exists but projects are smaller in scale or involve lower sequencing intensity. Meanwhile, the mobilisation of processed eDNA-derived biodiversity data into secondary platforms remains limited: only 25 datasets in OBIS contained the DNA-derived data extension from European marine waters, and just 15 percent of questionnaire respondents reported submitting such data to biodiversity portals.
The way forward, the authors argue, lies in a structured framework combining three complementary sets of principles. The FAIR principles, ensuring data are Findable, Accessible, Interoperable and Reusable, form the technical foundation, drawing on Darwin Core and MIxS standards alongside GBIF guidelines for publishing DNA-derived data. The CARE principles, emphasising Collective benefit, Authority to control, Responsibility and Ethics, address Indigenous data governance and responsible sample stewardship. The TRUST principles, covering Transparency, Responsibility, User focus, Sustainability and Technology, provide criteria for repository reliability and long-term digital preservation. Recent work by Takahashi and colleagues on Making eDNA FAIR has already produced a comprehensive metadata checklist integrating these standards with new terms tailored specifically to eDNA workflows, and core terms of MIxS and Darwin Core have been mapped to improve interoperability between the sequence and biodiversity data infrastructures.
Importantly, the authors stress that standardisation does not imply a single universal eDNA protocol. Rather, it entails a portfolio of context-dependent, transparent and well-documented methodological approaches that are comparable because they adhere to shared reporting principles. PCR conditions and primer sequences should be consistently reported, as they are a critical determinant of taxonomic coverage and amplification bias. The cost of poor metadata standardisation, in terms of wasted research investment, duplicated efforts and reduced funding efficiency, was not quantified in this study, but the authors describe it as a substantial hidden burden on the research ecosystem.
As Europe moves toward coordinated aquatic biodiversity monitoring at scale, the message from this assessment is unambiguous. eDNA can become a cornerstone of conservation strategy, environmental policy and rigorous evaluation of restoration interventions, but only if the data infrastructure catches up with the science. Coordinated efforts between field and laboratory method experts, data custodians and policymakers are essential to embed minimum metadata requirements into harmonised reporting frameworks, ensuring that high-quality metadata becomes a natural outcome of methodological compliance rather than an afterthought. The technology is ready. The question now is whether the community can align its incentives, training and repositories to make every eDNA dataset as reusable as the science it enables.
Subject of Research: Navigating the European aquatic eDNA landscape: Opportunities for metadata standardisation and data mobilisation
Article Title: Navigating the European aquatic eDNA landscape: Opportunities for metadata standardisation and data mobilisation
Article References: Kavakiotis, I., Woollard, P., Babo, C., Egge, E., Krawczyk, D., Laamanen, T., Paupério, J., Bacela-Spychalska, K., Pade, N., Costa, F. O., Grabowski, M., Norros, V., Meissner, K., & Papakostas, S. (2026). Navigating the European aquatic eDNA landscape: Opportunities for metadata standardisation and data mobilisation. Metabarcoding and Metagenomics, 10, Article e173612. https://doi.org/10.3897/mbmg.10.173612
Image Credits: AI Generated
Keywords: Navigating, European, aquatic, eDNA, landscape, Opportunities, metadata, standardisation, data, mobilisation, scientific research
Cite Scienmag News
Margaret Porter. (October 17, 2026). Europe’s eDNA revolution is drowning in bad metadata, landmark study warns. Scienmag. https://scienmag.com/europes-edna-revolution-is-drowning-in-bad-metadata-landmark-study-warns/
Margaret Porter. "Europe’s eDNA revolution is drowning in bad metadata, landmark study warns." Scienmag, 17 October 2026, https://scienmag.com/europes-edna-revolution-is-drowning-in-bad-metadata-landmark-study-warns/. Accessed 17 October 2026.
Margaret Porter. "Europe’s eDNA revolution is drowning in bad metadata, landmark study warns." Scienmag. October 17, 2026. https://scienmag.com/europes-edna-revolution-is-drowning-in-bad-metadata-landmark-study-warns/


