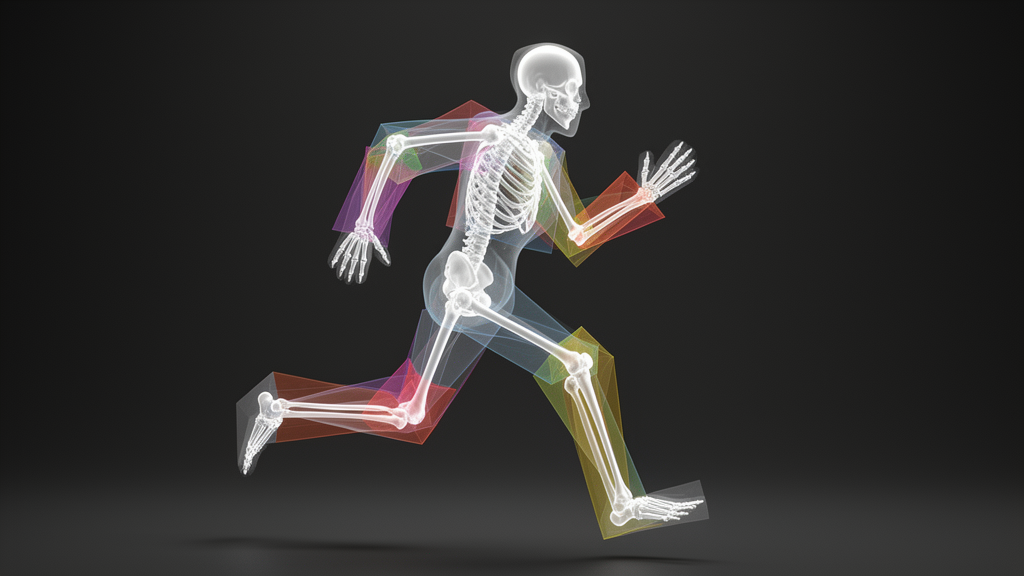
A self-supervised computational framework named AMST consistently outperforms state-of-the-art methodologies in skeleton-based action recognition across benchmark evaluations, yielding substantial performance gains across diverse evaluation metrics. In extensive experiments conducted on the NTU RGB+D60, NTU RGB+D120, and PKU-MMD benchmark datasets, the framework demonstrated superior performance compared to existing self-supervised methods on downstream action recognition tasks, confirming the transferability of its learned representations.
While skeleton-based action recognition is inherently robust to variations in background and viewpoint, existing self-supervised learning approaches often suffer from temporal redundancy and noisy spatial structures.
To resolve these vulnerabilities, the researchers designed AMST as an Attention Mask Spatio-Temporal framework utilizing a triple-stream architecture with a shared common encoder. The architecture incorporates an anchor stream that preserves full semantics alongside two specialized masking streams. A temporal masking stream employs Adaptive Temporal Modeling to select motion-salient frames, while a spatial masking stream uses Adaptive Spatial Modeling to capture key joint dependencies across the skeleton.
All three streams sharing the common encoder are optimized via an objective based on Barlow Twins, enforcing representation consistency across views while reducing feature redundancy. By combining adaptive spatio-temporal masking with redundancy reduction, the framework learns robust, transferable skeleton representations that consistently exceed prior self-supervised benchmarks across diverse evaluation metrics.
The empirical verification of the framework relies on downstream action recognition evaluations across three established benchmark collections: NTU RGB+D60, NTU RGB+D120, and PKU-MMD. Across these testing suites, the learned representations demonstrated robust transferability and achieved consistent improvements over existing self-supervised baselines across diverse evaluation metrics, confirming the effectiveness of combining adaptive spatio-temporal masking with redundancy-reducing self-supervised objectives.
Subject of Research: Self-supervised skeleton-based action recognition
Article Title: Self-supervised skeleton action recognition with attention-guided spatio-temporal masking
Article References: Kou, S., Chen, H., Cui, X., & Li, X. (2026). Self-supervised skeleton action recognition with attention-guided spatio-temporal masking. International Journal of Machine Learning and Cybernetics, 17(11), Article 521. https://doi.org/10.1007/s13042-026-03369-x
Image Credits: AI Generated
DOI: 10.1007/s13042-026-03369-x
Keywords: skeleton action recognition, self-supervised learning, spatio-temporal masking, Barlow Twins, attention mechanisms, action recognition, computer vision, machine learning, Self-supervised, skeleton, action, recognition
Cite Scienmag News
Blake Davidson. (November 7, 2026). Attention-Guided Spatio-Temporal Masking Improves Self-Supervised Skeleton Action Recognition. Scienmag. https://scienmag.com/attention-guided-spatio-temporal-masking-improves-self-supervised-skeleton-action-recognition/
Blake Davidson. "Attention-Guided Spatio-Temporal Masking Improves Self-Supervised Skeleton Action Recognition." Scienmag, 7 November 2026, https://scienmag.com/attention-guided-spatio-temporal-masking-improves-self-supervised-skeleton-action-recognition/. Accessed 10 November 2026.
Blake Davidson. "Attention-Guided Spatio-Temporal Masking Improves Self-Supervised Skeleton Action Recognition." Scienmag. November 7, 2026. https://scienmag.com/attention-guided-spatio-temporal-masking-improves-self-supervised-skeleton-action-recognition/