

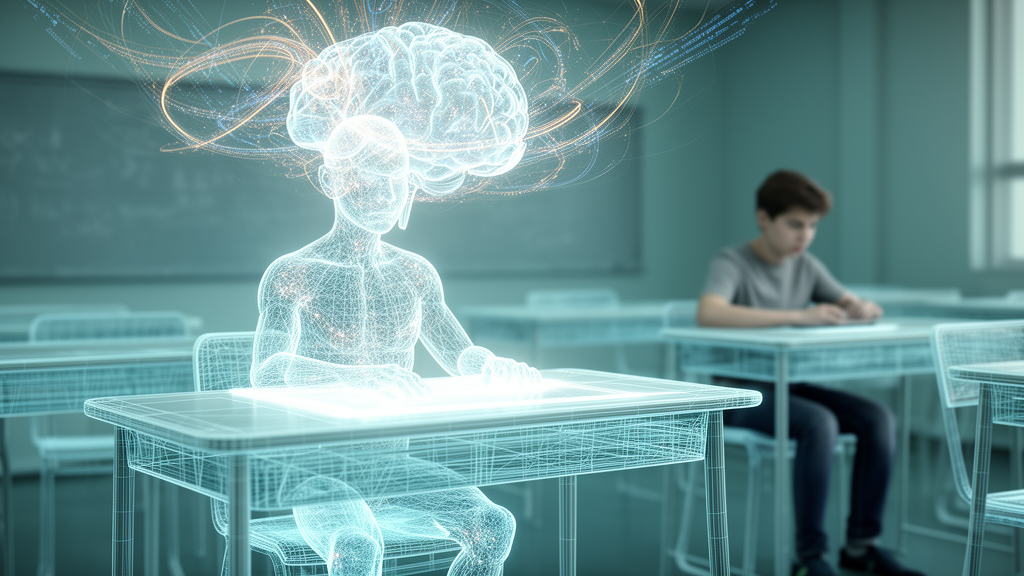
Metacognition, the capacity to think about one’s own thinking, has long been celebrated as perhaps the highest achievement of learning, yet researchers have struggled to study how it actually develops over time. Now a study published in Frontiers in Psychology on 23 October 2026 offers an unusual way forward: a computer simulation in which hundreds of synthetic students, each governed by explicit mathematical rules, climb a five-level ladder of metacognitive skill while researchers watch what happens under different teaching conditions. The framework, called AMERT-D, was designed and internally evaluated by Chuanhui Guo of Quanzhou Preschool Education College in China, and it represents one of the first attempts to bring digital-twin-inspired modeling to metacognition research in higher education. Crucially, the author emphasizes that every number the simulation produces is a model-generated hypothesis, not an observation of real students.
The theoretical backbone of the work is the hierarchical AMERT model, developed by Willison and colleagues through an integrative review of the metacognition literature. AMERT organizes metacognitive development into five progressive levels: self-awareness of cognition, self-monitoring, self-evaluation, self-regulation, and finally self-transfer, the ability to consciously apply metacognitive skills in entirely novel contexts. The model’s great strength is its explicit hierarchy, in which higher levels are said to depend on mastery of lower ones. Its great weakness, according to the new study, is that it describes states rather than processes. AMERT tells us what the levels are, but not how a learner moves from one to the next, and decades of theory have accumulated faster than the field’s ability to test them empirically in classrooms.
Guo identifies three obstacles that have kept sophisticated metacognition theory and messy educational reality apart. First, definitional and measurement crises: self-report questionnaires are inherently biased and cannot capture the full dynamics of metacognitive processes. Second, ethical and practical constraints: long-term interventions with human participants are costly, slow, and sometimes ethically problematic, which is precisely why longitudinal training studies remain rare. Third, the theory-practice chasm: complex models like AMERT remain abstract conceptualizations rather than implementable educational systems. The study responds to all three at once by building a virtual laboratory, a simulation environment where developmental trajectories that would take years to observe in people can be generated, stress-tested, and revised in hours of computation.
The term digital twin requires careful handling here. In engineering and manufacturing, a digital twin is a dynamic virtual representation of a physical system, updated through real-time data with bidirectional coupling between the physical and virtual entities. Guo explicitly adopts a different category, the simulation-based digital twin, which instantiates a theoretical model within an agent-based architecture to explore emergent behaviors and generate hypotheses. There is no physical counterpart, no real-time data feed, and no coupling with actual learners. The framework is described as a conceptual precursor, a foundation on which future data-driven digital twins of students could eventually be built once the model has been calibrated with longitudinal classroom data.
Technically, AMERT-D consists of three interconnected layers. The metacognitive layer operationalizes the five AMERT levels as continuous variables scored from 0 to 100, each with static attributes set at initialization and dynamic attributes updated every simulation tick. The simulation layer, implemented in NetLogo 6.4.0, represents each student as a computational agent with attributes including prior knowledge, self-efficacy, effort allocation, academic performance, and the current phase of self-regulation, following Winne and Hadwin’s influential four-phase model of task definition, goal-setting, strategy enactment, and adaptation. The instructional strategy layer models instructor feedback, peer feedback, and task complexity as environmental forces. Instructor feedback strength adapts to the learner, being scaled by the complement of normalized self-efficacy so that agents with lower confidence receive more intense guidance.
The heart of the framework is its transition mechanism. An agent can only move from one AMERT level to the next when three conditions are met simultaneously: its score for the current level must reach a mastery threshold of 60 on the 0-to-100 scale, it must have accumulated a minimum amount of experience at that level, ranging from 30 ticks for the move from self-awareness to self-monitoring up to 60 ticks for the move from self-regulation to self-transfer, and it must receive an external readiness signal from feedback. Scores update each tick according to a learning rate of 0.05, a feedback strength parameter, the agent’s current effort, and a small stochastic noise term. This threshold-based progression encodes the AMERT hierarchy’s core assumption directly into the simulation’s mathematics.
Before running any experiments, Guo validated the framework’s conceptual content through a modified Delphi process with 12 experts drawn from educational technology, cognitive psychology and the learning sciences, instructional design, and computational modeling across five institutions. Round two produced strong consensus, with Kendall’s coefficient of concordance reaching 0.82, and the operationalizability component, the one most critical for computational implementation, achieved a mean rating of 4.32 out of 5. The internal consistency of the simulation itself was then checked using a Graph Neural Network trained on 14 behavioral features from 200 agents. The classifier distinguished the four computational learner archetypes, labeled deep, surface, low-effort, and general, with 89 percent accuracy. The author is candid that this high accuracy is largely a mathematical consequence of the deliberately different starting parameters and demonstrates internal coherence, not behavioral realism.
The scenario experiments, run with 100 agents over 150 ticks and repeated 50 times per condition, produced several striking patterns. The hybrid scenario, combining instructor feedback, peer feedback, and high task complexity, achieved the highest weighted AMERT average of 3.86 and a modeled self-transfer rate of 38 percent, compared with just 2 percent in the base scenario. Scenarios incorporating instructor feedback were associated with a 38 percent reduction in the simulated metacognitive gap, the difference between an agent’s self-assessment and its actual performance. Peer feedback alone did not significantly outperform the base condition, though the author notes this null result is partly an artifact of modeling peer influence as a simple average of neighbors’ performance, stripped of explanatory depth and collaborative sense-making. Task complexity showed an inverted-U effect, stimulating metacognitive growth at moderate levels and inhibiting it when demands became excessive.
Perhaps the most thought-provoking pattern is what the author calls a Matthew Effect. When all agent profiles received identical interventions, the gap between the high-performing deep archetype and the low-effort archetype widened rather than narrowed, increasing from 1.88 in the base condition to 2.41 in the hybrid scenario. Guo stresses that this widening is a mathematically expected consequence of the threshold-based progression mechanism: in any cumulative system where higher-level mastery depends on lower-level mastery and agents start from different points, uniform interventions will produce diverging outcomes. The pattern held across threshold values from 40 to 80, suggesting it is a structural property of the model’s logic rather than an artifact of one parameter choice. As a hypothesis, it raises uncomfortable questions about whether one-size-fits-all instruction might amplify existing disparities, but it awaits testing with real students.
The study also introduces metacognitive resilience as a candidate simulation-based indicator, operationalized as the stability of higher-order metacognitive processes under increasing task difficulty. In the dynamic complexity scenario, where task demands escalated in stages, agents showed an 18 percent modeled drop in self-regulation and a 32 percent increase in the metacognitive gap at the highest difficulty, with deep-archetype agents recovering quickly while low-effort agents nearly ceased regulating altogether. Whether resilience is a distinct construct, separable from absolute metacognitive level, remains an open empirical question. The author is equally clear about the broader limitations: the expert panel may reflect regional perspectives, the 150-tick duration corresponds to no real classroom timescale, and the reported effect sizes describe properties of the computational model, not of educational reality. What AMERT-D delivers is a transparent, reproducible pipeline from theory to testable prediction, and an invitation for researchers to start calibrating its parameters against the only data that ultimately matter, the trajectories of actual learners.
Subject of Research: Educational psychology and computational modeling of metacognition in higher education
Article Title: Design and evaluation of an agent-based digital-twin-inspired simulation for metacognition research in higher education
Article References: Guo, C. (2026). Design and evaluation of an agent-based digital-twin-inspired simulation for metacognition research in higher education. Frontiers in Psychology, 17, Article 1914901. https://doi.org/10.3389/fpsyg.2026.1914901
Image Credits: AI Generated
DOI: 10.3389/fpsyg.2026.1914901
Keywords: metacognition, digital twin, agent-based simulation, higher education, self-regulated learning, AMERT model, NetLogo, educational psychology, Design, evaluation, agent-based, digital-twin-inspired
Cite Scienmag News
Courtney Benton. (October 24, 2026). Virtual Students, Real Theory: Digital Twin Simulation Puts Metacognition to the Test. Scienmag. https://scienmag.com/virtual-students-real-theory-digital-twin-simulation-puts-metacognition-to-the-test/
Courtney Benton. "Virtual Students, Real Theory: Digital Twin Simulation Puts Metacognition to the Test." Scienmag, 24 October 2026, https://scienmag.com/virtual-students-real-theory-digital-twin-simulation-puts-metacognition-to-the-test/. Accessed 24 October 2026.
Courtney Benton. "Virtual Students, Real Theory: Digital Twin Simulation Puts Metacognition to the Test." Scienmag. October 24, 2026. https://scienmag.com/virtual-students-real-theory-digital-twin-simulation-puts-metacognition-to-the-test/


