Computer vision researchers Abdulaziz Aldegheishem, Zaied Alhaj, and Nabil Alrajeh have introduced SC-CADA-YOLO26n, a compact four-scale road-object detection architecture designed to improve the identification of small and distant road hazards without overburdening embedded vehicle hardware. Published in Discover Computing, the study pairs a nano-scale YOLO26 backbone with a stride-4 prediction head, perspective-guided feature alignment, and quality-capped target assignment. In three-seed evaluations on a stratified partition of the KITTI benchmark at 1280 by 1280 pixel resolution, the model attained an overall mean average precision of 0.7534 across intersection-over-union thresholds from 0.50 to 0.95 under one-to-many supervision with non-maximum suppression. Crucially, average precision on small objects reached 0.6720 compared to 0.5743 for the unmodified baseline. Across a complementary single-run test on a 100,000-image derivative of the BDD100K dataset, the complete network recorded an overall mean average precision of 0.325, establishing an empirical foundation for coordinating fine-resolution feature extraction with geometric scene constraints.
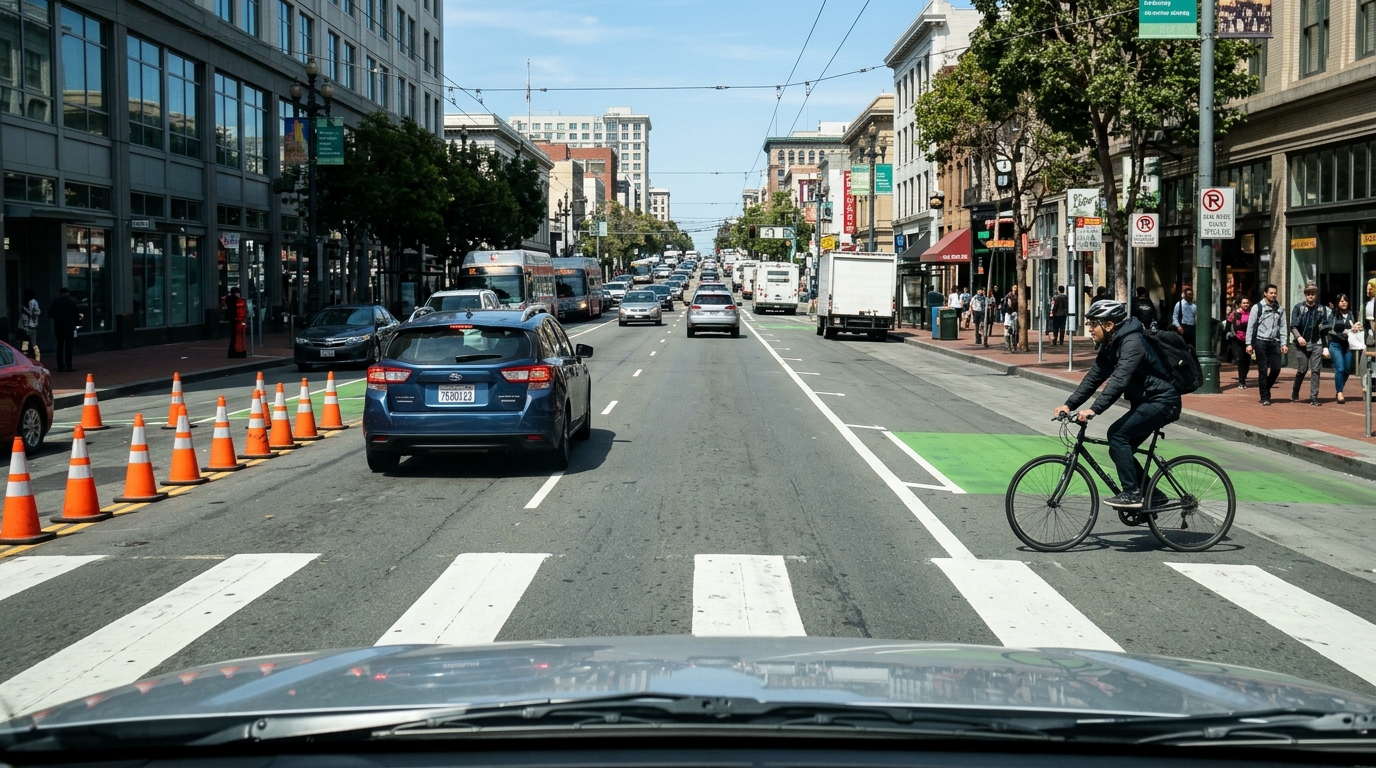
Detecting distant pedestrians, small road users, and elevated traffic signals represents a fundamental challenge for visual perception in autonomous driving and advanced driver-assistance systems. While camera sensors provide rich semantic data at lower financial costs than active ranging sensors, forward-facing road cameras must contend with rapid illumination changes, weather shifts, heavy occlusions, and severe class imbalances. Standard single-stage and two-stage deep architectures, including Faster R-CNN, SSD, and iterative releases of the YOLO family, traditionally struggle with tiny visual targets because progressive downsampling operations across convolutional layers destroy low-level texture and edge boundaries before representations reach the final detection heads. Although recent task-aligned detectors such as RT-DETR and specialized variants like RS-YOLO, PV-YOLO, and FRCP-YOLO have incorporated multi-scale feature pyramids or high-resolution prediction branches, naively enlarging feature resolutions expands the pool of candidate anchor positions, often diluting training gradients, introducing label noise, and destabilizing convergence across imbalanced real-world driving datasets.
To resolve these coupled bottlenecks, the authors built SC-CADA-YOLO26n upon the nano-scale YOLO26 model implemented in Ultralytics 8.4.84, preserving a compact parameter footprint of 2.547 million weights. Rather than relying solely on conventional stride-8, stride-16, and stride-32 heads, the architecture incorporates a high-resolution P2 branch operating at stride 4, constructing a complete four-scale pyramid across strides 4, 8, 16, and 32. At nano width scaling, the fused feature tensors at the P2 and P3 levels supply 32 and 64 channels, respectively, preserving the granular spatial coordinates required to localize tiny objects. The detection head is configured in an end-to-end multi-task mode that concurrently predicts continuous bounding-box side distances using a direct normalized L1 loss rather than a distribution focal loss formulation. Pretrained baseline weights initialize the backbone and detection subnets, while all newly introduced alignment and conditioning layers utilize dedicated near-identity initialization routines to safeguard pretrained feature representations during early training epochs.
The core spatial adaptation mechanism is self-calibrated perspective-conditioned condition-adaptive deformable alignment, designated SC-P-CADA, applied immediately following feature fusion at the P2 and P3 levels. Unlike standard deformable convolution schemes that alter convolutional kernel sampling locations throughout the feature hierarchy, SC-P-CADA functions as a post-fusion residual resampling block. Each module first projects incoming feature tensors through a pointwise one-by-one convolution, batch normalization, and SiLU activation to create an intermediate representation with reduced hidden channels. Crucially, the module incorporates an image-space perspective descriptor combining normalized planar coordinates, an upper-canvas vertical gradient, and an exponential term measuring vertical proximity to a learned horizon parameter. The horizon value is bounded between 0.25 and 0.65 of normalized canvas height and initialized at 0.42. During optimization, two independent global horizon scalars are learned across the entire training corpus for the P2 and P3 levels, allowing the alignment offsets to adapt to scale-dependent geometry while strictly sharing horizon parameters across images.
Building upon this perspective descriptor, SC-P-CADA employs a two-layer convolutional offset generator alongside a global-average-pooled channel conditioning path. A perspective adapter processes the concatenated feature and coordinate descriptors, applying a perspective gain factor of 0.75 to calculate a two-dimensional displacement field and a spatial channel modulation gate. To prevent unstable grid deformations, the horizontal and vertical offsets are explicitly bounded to two feature pixels per axis via hyperbolic tangent scaling. Bilinear interpolation then warps the projected features across the displaced grid using border padding conventions. The warped representation passes through a depthwise three-by-three convolution, batch normalization, SiLU activation, and a pointwise one-by-one convolution before being modulated by the adaptive channel gate. Because residual reconstruction weights and terminal adapter parameters are initialized to zero, the module functions as a near-identity transformation at the start of training, introducing geometric warping smoothly as optimization advances without disrupting pretrained network features.
Complementing the spatial alignment module, the researchers developed perspective-quality scale-and-rarity-aware target assignment, abbreviated as PQ-SRATA, to regulate positive candidate selection during training. Under standard task-aligned assignment protocols, candidate anchors are scored by combining detached classification probabilities and complete intersection-over-union overlaps. PQ-SRATA dynamically adjusts candidate allocations by evaluating normalized object bounding box area, training-set class rarity derived from effective-number formulations, and an image-space perspective score based on vertical centroid positions relative to the mean learned horizon. Starting from a base allocation of ten candidate anchors, small objects can receive up to two additional positive locations, while class rarity and horizon proximity can each contribute one candidate, capping the requested expansion at fourteen. To prevent the inclusion of poorly aligned background anchors, the candidate pool is strictly restricted: only anchors whose alignment scores reach at least 18 percent of the top candidate score are retained, enforcing an effective positive candidate count between 3 and 14.
To balance gradient updates without destabilizing optimization, PQ-SRATA couples candidate selection with a mean-preserving foreground reweighting mechanism. Positive anchors inherit multiplicative weights combining class rarity, object area scaling, and perspective proximity, adjusted through a curriculum coefficient that ramps up during early training and remains fully active during high-resolution refinement. To prevent unnormalized weights from artificially inflating aggregate positive supervision relative to background samples, the foreground multipliers are normalized against the sum of soft target scores across all foreground anchors. The resulting coefficients are constrained to a safety range of 0.75 to 2.50, renormalized, and applied to positive classification, bounding-box regression, and side-distance regression losses. Negative classification terms retain an unmodified unit weight, ensuring background suppression gradients remain stable. Optimization minimizes an objective weighting bounding box loss by 5.63, classification loss by 0.56, and side distance loss by 9.04, progressively shifting training emphasis from dense one-to-many supervision to native one-to-one prediction.
Experimental validation was conducted on independently partitioned derivatives of the KITTI and BDD100K benchmarks, each partitioned into 80 percent training, 10 percent validation, and 10 percent testing subsets via greedy multilabel stratification with a split seed of 20,260,628. The KITTI dataset comprised 7,481 annotated images spanning eight categories, whereas BDD100K encompassed 100,000 images covering ten classes. An initial data integrity audit detected and grouped four exact duplicate image pairs and removed two duplicate bounding boxes in BDD100K. Training utilized a coarse-to-fine two-stage schedule optimized via MuSGD with a momentum factor of 0.947 and cosine learning rate decay without restarts. Stage 1 trained at nominal 768 by 768 resolution with mosaic and mixup augmentations and an initial learning rate of 0.0054. Stage 2 conducted high-resolution refinement at 1280 by 1280 resolution using rectangular batches, disabled mosaic blending, reduced geometric perturbations, and a learning rate of 0.0005, initiating refinement from validation-selected Stage 1 checkpoints.
On the frozen 748-image KITTI test split, SC-CADA-YOLO26n demonstrated consistent performance gains across three independent optimization seeds (seeds 44, 64, and 84). Under one-to-many inference with non-maximum suppression, the full model achieved an overall mean average precision of 0.7534 with a sample standard deviation of 0.0014 and a 95 percent confidence interval of 0.7500 to 0.7568, outperforming the baseline YOLO26n score of 0.7080. Detailed size-stratified evaluations confirmed that small-object average precision rose from 0.5743 in the baseline to 0.6720 in the full architecture. In component ablations, adding only the high-resolution P2 stride-4 head raised small-object precision to 0.6000 but reduced overall mean average precision, demonstrating that finer resolution alone introduces localization ambiguity unless paired with guided assignment. Furthermore, the native one-to-one end-to-end path achieved 0.7460 without post-processing non-maximum suppression, retaining roughly 99 percent of one-to-many accuracy, while test-time augmentation yielded 0.7547 at the expense of nearly tripling inference wall time.
Evaluation on the 10,000-image BDD100K test partition recorded an overall mean average precision of 0.325, with car reaching 0.525 and bus achieving 0.483, but exposed severe limits under extreme class scarcity. With only 140 train instances in the training set and 20 in testing, the detector yielded zero precision and an average precision of 0.0003, confirming that algorithmic weighting cannot replace missing visual diversity. Complexity profiling measured 2.547 million parameters and 28.859 counted GFLOPs at 1280 resolution, with single-image inference averaging 38.362 milliseconds on an NVIDIA A100. While the end-to-end path halved post-processing time, increased inference latency yielded negligible wall-time gains. Crucially, the authors note that learned horizons represent image-space geometric priors rather than metric depth, and exported model discrepancies indicate that embedded deployment requires verified on-device benchmarking before real-world adoption.
Subject of Research: Compact road-object detection using perspective alignment and quality-aware target assignment
Article Title: Compact road-object detection with self-calibrated perspective alignment and quality-aware assignment
Article References: Aldegheishem, A., Alhaj, Z., & Alrajeh, N. (2026). Compact road-object detection with self-calibrated perspective alignment and quality-aware assignment. Discover Computing, 29(1), Article 850. https://doi.org/10.1007/s10791-026-10796-5
Image Credits: AI Generated
DOI: 10.1007/s10791-026-10796-5
Keywords: object detection, autonomous driving, computer vision, YOLO, deep learning, convolutional neural networks, KITTI benchmark, BDD100K dataset, Compact, road-object, detection, self-calibrated
Cite Scienmag News
Blake Davidson. (November 8, 2026). Compact Road Object Detector Leverages Perspective Alignment and Quality Aware Assignment. Scienmag. https://scienmag.com/compact-road-object-detector-leverages-perspective-alignment-and-quality-aware-assignment/
Blake Davidson. "Compact Road Object Detector Leverages Perspective Alignment and Quality Aware Assignment." Scienmag, 8 November 2026, https://scienmag.com/compact-road-object-detector-leverages-perspective-alignment-and-quality-aware-assignment/. Accessed 8 November 2026.
Blake Davidson. "Compact Road Object Detector Leverages Perspective Alignment and Quality Aware Assignment." Scienmag. November 8, 2026. https://scienmag.com/compact-road-object-detector-leverages-perspective-alignment-and-quality-aware-assignment/