


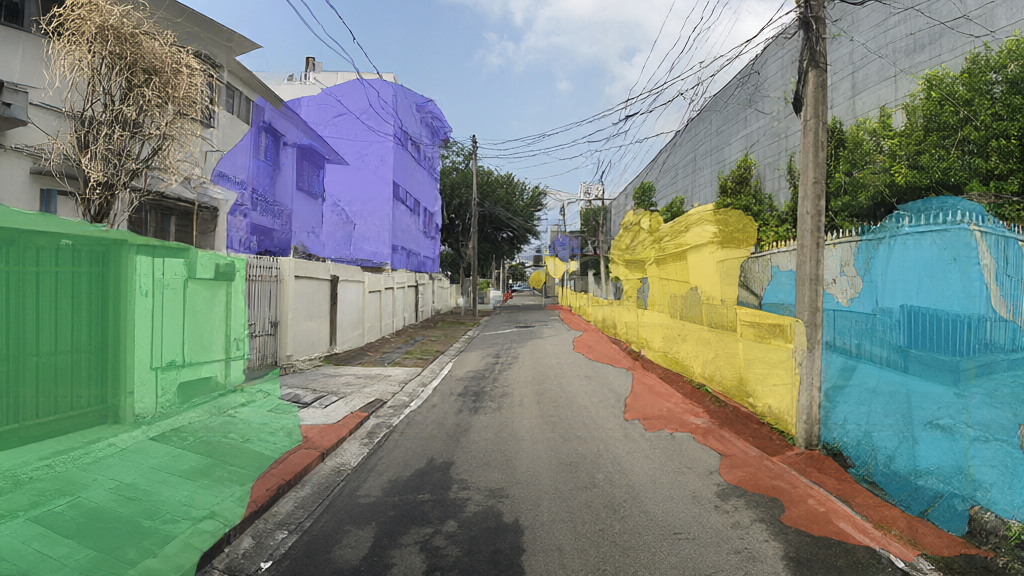
Instance segmentation, a core task in computer vision that involves identifying and delineating individual objects within a scene, has become increasingly critical for applications ranging from autonomous driving to medical imaging. While deep learning has driven significant advancements in this field, the prevailing state-of-the-art models often rely on complex architectures that demand substantial computational resources. This high computational cost presents a barrier to real-time deployment, particularly in latency-sensitive environments where rapid processing is essential for safety and efficiency.
Addressing this challenge, researchers from the Department of Electrical and Computer Engineering at Democritus University of Thrace in Greece have proposed a new compact model designed to balance accuracy with efficiency. The study, published in the journal Multimedia Tools and Applications, introduces a novel convolutional encoder named DDMnet, which stands for depthwise separable Dilated Multires Network. The primary objective of this work is to develop a system that maintains high segmentation performance while significantly reducing the computational burden associated with existing methods.
The proposed architecture integrates the DDMnet encoder with the Mask2Former segmentation framework. Mask2Former is a well-established universal image segmentation model that utilizes transformer-based attention mechanisms to process image features. By replacing the standard encoder components with the proposed DDMnet, the researchers aim to leverage the strengths of both the efficient convolutional design and the robust segmentation capabilities of the transformer-based decoder. This hybrid approach is intended to create a pipeline that is both lightweight and effective for general-purpose segmentation tasks.
At the core of the DDMnet design is the use of depthwise separable convolutions. This technique decomposes standard convolution operations into two separate steps: a depthwise convolution that applies a single filter per input channel, followed by a pointwise convolution that combines the outputs. This decomposition drastically reduces the number of parameters and floating-point operations required, making the model more suitable for hardware with limited processing power. The inclusion of “dilated” or atrous convolutions further enhances the network’s ability to capture multi-scale context without increasing the number of parameters, allowing the model to understand both fine-grained details and broader scene structures.
The “Multires” aspect of the network name refers to its ability to process features at multiple resolutions. By maintaining high-resolution feature maps alongside lower-resolution, semantically rich features, the network can better handle objects of varying sizes. This is particularly important in complex scenes where small, distant objects must be distinguished from large, foreground objects. The integration of these multi-resolution features ensures that the segmentation masks are precise and that the model does not lose spatial information during the downsampling process typical of convolutional neural networks.
To validate the effectiveness of the proposed model, the researchers evaluated DDMnet on two prominent benchmark datasets: Cityscapes and ADE20K. Cityscapes is a large-scale dataset focused on urban street scenes, containing images of cars, pedestrians, cyclists, and other traffic participants, making it highly relevant for autonomous driving research. ADE20K, on the other hand, is a more diverse dataset that includes a wide variety of indoor and outdoor scenes with a larger number of object categories, providing a more comprehensive test of the model’s generalization capabilities.
The study reports that the DDMnet-based model achieves performance levels close to those of state-of-the-art methods on these benchmarks. While the exact numerical metrics are detailed in the full publication, the abstract emphasizes that the model delivers competitive accuracy while maintaining low computational complexity. This suggests that the trade-off between model size and segmentation quality is favorable, offering a viable alternative to heavier models that may be impractical for real-time applications. The results indicate that the proposed architecture successfully preserves the essential features needed for accurate instance segmentation without the excessive overhead of larger networks.
The potential for real-time deployment is a key highlight of this research. In applications such as self-driving cars, the system must process video frames quickly to make split-second decisions. A model that requires significant computational power may introduce latency that compromises safety. By designing a lightweight encoder, the researchers aim to enable faster inference times, allowing the segmentation pipeline to run on edge devices or in environments where computational resources are constrained. This focus on efficiency aligns with the broader trend in computer vision toward developing models that are not only accurate but also practical for on-device implementation.
The authors, Nikolaos Detsikas, Christos Chatzisavvas, Nikolaos Mitianoudis, and Ioannis Pratikakis, acknowledge the support of NVIDIA Corporation for providing an RTX A6000 GPU used in the research. The code and model implementations are made available through a public GitHub repository, facilitating reproducibility and further exploration by the research community. The datasets used for evaluation, Cityscapes and ADE20K, are also publicly available, ensuring that the results can be verified and compared against other methods in the field.
This work contributes to the ongoing effort to make advanced computer vision techniques more accessible and efficient. By proposing a specific architectural modification that reduces computational load without sacrificing significant accuracy, the researchers provide a useful tool for developers and researchers working on real-time segmentation systems. The integration of depthwise separable convolutions with multi-resolution processing offers a promising direction for future research, potentially leading to even more efficient models that can handle increasingly complex visual tasks in real-world applications.
Subject of Research: Computer Vision
Article Title: A lightweight depthwise separable Dilated Multires Network (DDMnet) for instance segmentation
Article References: Detsikas, N., Chatzisavvas, C., Mitianoudis, N., & Pratikakis, I. (2026). A lightweight depthwise separable Dilated Multires Network (DDMnet) for instance segmentation. Multimedia Tools and Applications, 85(9), Article 759. https://doi.org/10.1007/s11042-026-21907-1
Image Credits: AI Generated
DOI: 10.1007/s11042-026-21907-1
Keywords: instance segmentation, deep learning, computer vision, efficient networks, autonomous driving, lightweight, depthwise, separable, Dilated, Multires, Network, DDMnet
Cite Scienmag News
Blake Davidson. (October 2, 2026). Researchers propose lightweight DDMnet for efficient instance segmentation. Scienmag. https://scienmag.com/researchers-propose-lightweight-ddmnet-for-efficient-instance-segmentation/
Blake Davidson. "Researchers propose lightweight DDMnet for efficient instance segmentation." Scienmag, 2 October 2026, https://scienmag.com/researchers-propose-lightweight-ddmnet-for-efficient-instance-segmentation/. Accessed 2 October 2026.
Blake Davidson. "Researchers propose lightweight DDMnet for efficient instance segmentation." Scienmag. October 2, 2026. https://scienmag.com/researchers-propose-lightweight-ddmnet-for-efficient-instance-segmentation/


